


| # | User | Rating |
|---|---|---|
| 1 | Benq | 3676 |
| 2 | jiangly | 3670 |
| 3 | Kevin114514 | 3657 |
| 4 | maroonrk | 3355 |
| 5 | Um_nik | 3353 |
| 6 | squareOf105 | 3346 |
| 7 | tourist | 3343 |
| 8 | strapple | 3324 |
| 9 | heuristica | 3322 |
| 10 | jiangbowen | 3291 |
| # | User | Contrib. |
|---|---|---|
| 1 | Qingyu | 158 |
| 2 | nik_exists | 150 |
| 2 | maspy | 150 |
| 4 | AmShZ | 143 |
| 5 | Um_nik | 141 |
| 6 | Errichto | 139 |
| 7 | adamant | 137 |
| 8 | BledDest | 133 |
| 8 | maroonrk | 133 |
| 10 | qwexd | 130 |


|
On
MikeMirzayanov →
2017-2018 ACM-ICPC, NEERC, Southern Subregional Contest, qualification stage (Online Mirror, ACM-ICPC Rules, Teams Preferred), 9 years ago
+11
J can be solved by binary search on the answer and using max flow to check if it can be done. For L, notice that in a valid tree, there is an edge between nodes a and b if and only if the sum of the size of a's set containing b and the size of b's set containing a is equal to n. Then once we have all the pairs which must be edges, we check if it forms a valid tree. |

|
+25
Can't tell if Reyna left their laptop logged in, or if someone else got randomly logged in like this guy, or if Reyna just sent their credentials to those "researchers". (Kappa) |
|
0
Definitely I think that codeforces rating changes too much based on recent contests (for experienced competitors). (Though congrats to yosupo on impressive recent perforomance.) For example, people always say "I hope I do well on this contest so I get high rating", and even top competitors have changes of 100-200 rating in one contest. But in chess, no one talks about the effect of a person's most recent games on their rating. At most they will look at trends over time, and I think that's how it should be with ratings... |
|
+28
I mean... you both have actual points. Best to leave your first paragraph out of the discussion. |
|
+21
Being original and being standard are different things. |
|
0
I thought the most natural interpretation was a probability distribution with large variance/standard deviation... |
|
+70
|
|
+15
For B, I remember at least that it was set at FARIO 2009 (a joint French-Australian contest) and the problem and solution was described in Last Supper from IOI 2012. I think it's one of the most standard problem that I haven't heard an official name for. |
|
+26
No according to last year. http://codeforces.me/blog/entry/45628?#comment-304527 |
|
+12
On myicpc. |
|
+63
Actually the joke isn't centered around what "a contestant" means. The joke is people who read Petr's blog hope that one day the will get mentioned. So ___ does something unique and worth mentioning... but he doesn't get mentioned by name! So he got "so close" but not close enough. ¯\_(ツ)_/¯ Sorry I made the joke a bit obtuse but it was a tradeoff between making it more understandable and making the delivery shorter and sharper. |
|
+79
radoslav11 so close. |
|
0
I can't check right now but I assumed it was the way cf does team ratings? http://codeforces.me/blog/entry/16986 |
|
+48
It's also the 'golden generation' for Australia (though they have next year too if they don't succeed this year). Besides JoeyWheeler, don't forget xxTastyHypeBeast666xx got 5th at IOI and AntiForest was one place off gold. Abyss's and antiforest's cf ratings are just deceptively low because they're sane and decide to sleep at nighttime ;) |
|
On
BledDest →
Educational Codeforces Round 21 + announcement of 2nd Hello Barcelona ACM-ICPC Bootcamp, 9 years ago
+31
I haven't read the problems but surely most of the time, whether or not you use unordered_set/map is largely orthogonal to the main point of solving the actual problem. So if you choose to use a data structure which is known to have a bad worst case, you really have no one to blame but yourself (and yes, even normal CF rounds have anti-hashing cases). But if for some reason you need the extra speed, you can just generate a random number and xor your usages of the unordered_set/map with it to prevent it from breaking on specific known cases. |
|
+33
Like someone said it's probably held at the same time as the on-site contest, and different countries hold APIO at different times so it's hard to avoid anyway. |
|
+14
Well that's another issue entirely and I think it's entirely unenforceable. For example say you accidentally (or "accidentally") have some code that accesses array out of bounds and crashes, but you only call it in a specific case. Then it acts as an assert. |
|
+46
At first I thought this was just a stupid idea. I'm pretty sure a similar idea was presented last year and it was shot down for being vague and unenforceable. But thinking a bit more, and reading closely, I think perhaps this rule is okay? For example, I thought at first that the following case would result in unfair judgement: Say there is a problem with a tree. A contestant incorrectly believes that node 0 will always end up with even degree, so she adds: and ends up with a crash judging result. Suddenly (I thought) the contestant is disqualified for discovering details about the test data! But actually this is okay by the rule, because if she fixes her solution to handle all cases where node 0 has odd degree, then she has not "adapted to specific test cases" but rather solved all cases with node 0 having odd degree. I hope that it will be clarified that doing this intentionally is also okay(?) That is, if you get WA, you are allowed to check what type of case it is getting WA on by submitting with asserts. Maybe this is already obvious to everyone else and I'm just thinking too hard >< (oh but also, there is still the problem of how to enforce the rule...) edit: actually I guess they could just actually go through with testing solutions on another data set with a different seed, and then manually check any solutions that get a different score/different correct subtasks. |
|
0
Ah I see now. Thanks for your help! |
|
+15
I believe it's this one. |
|
0
Is there no English version of the documentation? I can't find any, and google translate doesn't seem to work. |
|
+18
Depends on your machine. A safe estimate would be 108 per second. And typically you only need a few seconds to solve the problem. The 6 minutes is just to make sure everyone has time to fiddle with files and uploading etc. |
|
+23
Don't think about pixels. I was confused by this at first too, but in fact the problem statement does not mention pixels at all. Simply think of the points on the plane (0,0) and (100,100). |
|
+18
An alternative solution for D: We again use the observation that only cells within 150 can be coloured so there are at most 300*300 cells to keep track of. Suppose we are finding which squares are coloured by some firework of depth k, and we already know which squares are coloured by everything in the right 'subtree' (note there are at most 300*300). Then to get which squares are coloured by the left subtree, we can simply reflect them about the line formed by the the current firework. Thus we can colour any single path in the 'firework tree' (for example we could just dfs, recursing on only the right subtree every time) and then reflect the tree as we go back up. Then, the complexity, where S is the grid size, is O(S^2 * depth). A last detail is how do we do the reflection? There are only 4 types of flips depending on which way the current firework is going: up/down, left/right and the two diagonals. So we can just do some slight case bashing with the coordinates... |
|
+40
But like Batman said, everyone will ask "what does 'is it rated?' mean?" But no one cares to ask about another company sticker with the company name on it. Of course if you don't want to explain what it means every time, you'd prefer something more straightforward. But if you want people to find out and get interested in codeforces, then "is it rated?" is very good in its own way. |
|
On
MikeMirzayanov →
2016-2017 ACM-ICPC, NEERC, Southern Subregional Contest (Online Mirror, ACM-ICPC Rules, Teams Preferred), 10 years ago
0
> . < I meant to upvote because I had the same experience but I accidentally clicked downvote instead, sorry. |
|
On
MikeMirzayanov →
2016-2017 ACM-ICPC, NEERC, Southern Subregional Contest (Online Mirror, ACM-ICPC Rules, Teams Preferred), 10 years ago
+4
Are problems going to be shuffled since we can see the results? |
|
+6
The term is 'cross product'. |
|
0
It's simply dp[u][1] += dp[v][0] (right?) |
|
+69
why did you remove the anime background solution. This is how all solutions should be presented.
|
|
+98
I'm sorry but let me tell you what it looks like to me. amd makes contests for everyone. But a contest has hard problems so you decide to shit over his work. And it's not even in the thread for that contest, but you feel the need to do this in a totally unrelated thread (probably just to get some cheap contribution?) Am I wrong? Because to me it just seems entitled, disrespecful and inconsiderate, especially after this. |
|
+13
For n positions, let's try to find out what the first n/2 positions permute to. We could send n/2 subsets with 1 bit set in each of them, but then we wouldn't be able to send any more subsets with exactly 1 bit set (otherwise we wouldn't be able to tell them apart). Instead, let's send n/2 subsets with exactly 1 bit not set (exactly Now we repeat: for each group of n/2 positions, we send n/4 subsets with exactly
Okay I submitted it to yandex mirror and it got AC. Code: http://hastebin.com/udecimixug.cpp s = start, e = end, m = middle, p = current string we're adding or querying, v = current set of indices (ie indices which [s, e) maps to), x = left indices (ie indices which [s, m) maps to), y = right indices (ie indices which [m, e) maps to). |
|
+27
Calm down, you're overreacting. Just because people downvote a post you make doesn't mean they hate you. And I'm pretty sure tweety's post was made to cheer you up because things worked out in the end. |
|
0
Store the size of each component in your DSU. |
|
0
In the editorial, some of the diagrams for problem E are in the section for problem F. |
|
0
In the specific case of probabilistic soln yes the contestant 'should' use a fixed seed. But my point was more that it is unfair to take away 100 from the contestant after the contest is over, because the contestant was mislead to believe they had a correct solution so they didn't get to fix it. (And probabilistic soln was only an example, you can also consider solns which are barely within time limit.) You can fix this by taking away 100 during the contest with sufficient time remaining (which is an okay solution in IOI and an undesirable solution in timed contests) but my point is that it should be the contest setters responsibility to prevent or fix these things. And 'taking advantage of a security hole' or collusion is a strawman thanks. Looking at the memory usage when you are given the memory usage is not the same as collusion when the rules say "don't collude". |
|
+35
But how do you know whether it solves the problem? What if (as an example) there is a probabilistic solution to a problem which passes all the test cases 30% of the time. I submit once and get AC so I think it's correct but after the contest my solution is judged incorrect so I don't get the correct feedback during the competition. From what I heard from my team leader at IOI, this is why they "never take away 100 from a contestant after the contest is over" and it is the same here isn't it? Of course I agree something has to be done about gaming the submission feedback system for information, but I think it is the responsibility of the contest holder to make the problem and the system hard to game. (Which is not a new thing of course, some examples like only showing only first incorrect submission, or randomizing the order cases are given in feedback. And of course the problem setter must always be thinking about strong test cases.) I don't think punishing the contestant for using the system is the way to do it. |
|
+26
Wow, nice... but isn't it a bit dodgy to announce the 'special criteria' after the contest? :P |
|
+125
Come on, do you think users don't miss contests at the regular time? I haven't done a contest since 351. It's not because I didn't want to, it's because almost every contest is at 2:35am here. So yes, I'm a little bit salty that some people get almost all competitions at a decent time and then start complaining as soon as one competition is at a different time. (btw nothing personal to you, I just didn't know which comment to reply to so I just chose one) |
|
+36
Australia has it by now so I can only conclude you live on the moon. |
|
0
Yeah I think subtasks could be an interesting distinguishing feature for @coder compared to cf and tc. Having done IOI with subtasks in high school, it feels very different in a lot of open competitions where there is only AC or nothing. Of course we don't know how much they will use it in future contests but I think it has potential to make for some interesting contests. |
|
+8
Not everyone codes in an environment where they feel the same way. |
|
+10
Hmm... I'm pretty sure the green area is correct in my diagram. For example consider T = (4, 4), it is clear we should choose Q = (2, 3) as our bottom left point. But you're right, there are cases where the 'green' area is above instead of below. Specifically: the green area is below when Q is above (the line) PR, the green area is above when Q is below PR. Also, as you pointed out, there are cases where the lines actually don't intersect, which is when Q is on PR. So in fact there are cases where we should add candidates as we sweep from left to right, not just remove (and cases when we don't add or remove the candidate at all). Also, I think that we might actually not be able to consider only the two adjacent points when calculating when to add or remove a point. Probably we can't without more observations and maybe not at all. So actually, perhaps we can't do better than sqrt decomposition and the final solution is quite similar (or perhaps identical) to the half plane solution you described. |
|
+35
I have a solution to propose but I'm sure I made mistakes everywhere. Probably I even made a mistake immediately and this makes no sense. Firstly, we can restate the problem. Consider the graph (as in x-axis y-axis graph, not nodes + edges graph) of the cumulative sums. We wish to find the greatest (positive) rectangular area between two points. Secondly, consider two points which we are considering to use as the 'bottom left' corner of the rectangle, call them P = (x0, y0), Q = (x1, y1). Without loss of generality (wlog) let us say x1 > x0. Observe firstly that if x1 >= x0 and y1 >= y0, we will always choose P over Q. So we can say y1 < y0. I.e. we only need to consider a set of points that become lower as you move right. Now, which points T = (x, y) are there such that we wish to choose P over Q? I claim they are the points above the line going through (x0, y1) and (x1, y0). Diagram (we should choose P if T is above the red line, otherwise we should choose Q):
Now things get very hand-wavy and probably wrong or suboptimal. Let's call the red line the 'optimality line' of P and Q. Now we wish to solve the problem: given some potential 'bottom-left' points (call them 'candidates'), which is the best to use for some given query points? We can solve the problem for 2 candidates, but how do we solve it for more than 2? Consider 3 candidates. Call them P, Q, R in order of increasing x (remember that this means they are also in order of decreasing y). The optimality lines between P and Q, P and R and Q and R will all interesect at the same point. Example diagram (P = (0,4), Q = (2,3), R = (4,0):
Purple, green and orange areas are where R, Q and P are optimal respectively. I believe (*wave hands*) that it should be a similar case for any 3 candidates (*wave hands more*). So for any 3 candidates, we should be able to calculate the x coordinate at which the middle candidate becomes redundant. So now, we can sweep from left to right to answer queries. As we move, we calculate when each point will become redundant and remove them as necessary. (*wave hands vigorously*) To answer the queries themselves, we can binary search over the currently valid candidates (in order of the y values where they are optimal). blah blah something something it seems O(n lg n) maybe. (edit actually maybe n lg^2 n, who knows) (more edit: actually probably still n lg n) Okay I'm going to sleep now. I missed quite a few details and this is pretty poorly written because I had to change my solution as I realised some parts were wrong. Tomorrow I will probably wake up, read this and realise I'm totally insane >_> edit: 1) actually maybe you need a set to store candidates since you (might?) have to remove from the middle (?) so it would be O(n lg^2 n), 2) there's lot's of implicit details about keeping the candidates in order of decreasing y value, blah blah details something something mote edit: actually binary search is separate from set operations so probably still n lg n (okay I'm actually going to sleep now) |


|
0
But saving the suffix and prefix with maximum sum * length is not necessarily correct. Consider the case where the left 'subtree' is The suffix of the left subtree with greatest sum * length is the empty suffix with sum * length = 0. But the optimal solution is to take the entire string since the sum in the right subtree outweighs the negative sum in the left subtree. (And you can't fix this by adding it as a special case, the optimal suffix in the left subtree could be any length.) |
|
0
But what do you store for the prefix and suffix? The entire difficulty in the sum * length problem is that there isn't 1 optimal suffix/prefix. |
|
0
Did we have to register before the round to participate in it? I registered just now and can't submit :( |
|
+5
Ok I understand. You think f(x) = triangular number x. Actually f(x) = sum of first x-1 triangular numbers. So f(0) = 0, f(1) = 0, f(2) = 1, f(3) = 4, f(4) = 10 etc. So f(3) + f(3) + f(1) — f(2) — f(2) — f(0) = 4 + 4 + 0 — 1 — 1 — 0 = 6. 9 — 6 = 3 |
|
-16
Okay a = 1, b = 3, c = 3. Number of triples = 1*3*3 = 9. Number of impossible = 6 as you calculated. 9 — 6 = 3. Correct answer is 3. |
|
+3
"First idea that you want to count number of non triangles, instead of triangles." Seriously, there are only 2 sentences. Please don't downvote someone who is trying to help because you are so impatient you can't read more than 1 sentence (speaking to everyone). |
|
+8
Is anyone else with an automatic berth unable to register? I know JoeyWheeler and I got automatic berth and can't register but gongy qualified through round 1C and successfully registered... |
|
0
"All members who have not previously advanced – limited to the first 2,500 Competitors who register in the Arena" — from the rules linked in the post. |
|
+25
source: |


|
+2
But you didn't have to write a slow solution and generator, you can test your code however you want. In this case it was probably easier to make some cases by hand. Testing solutions well (finding the best way to test, making good tests, etc) is also a skill and a part of competition as much as solving problems in the first place. Of course it is up to the problem setters how strong their samples are but I don't think they should make them strong just because testing is 'hard'. |
|
+33
The first word in the problem statement is 'Connected'... |
|
+8
I guess I'll mention slightly differing(/slightly simpler?) solutions from the solutions given... For 'High Card Low Card (Platinum)' we don't need a custom segment tree, we can simply use a set to find the next lowest/highest card available: code. And for 'Counting Haybales' we don't even need lazy update (although one might prefer either way...), instead we just update ranges as normal and the 'actual value' at a leaf node is the sum of all nodes on the path to the root: code. In my range tree code, the ranges are [inclusive, exclusive), 'l', 'm' and 'r' stand for left, middle and right, 'n' stands for node', 'u' for update and 'q' for query. |
|
+20
The contest is still on... |
|
+5
Oops, you're right of course. I saw that the implementation had the same complexity without rollbacks, and since I always ignore the difference between O(a(n)) and O(logn) union-find in practice I carelessly assumed that it achieved the desired complexity. |
|
+10
If I understand correctly, we can simply store modifications (whose parent was changed and what it was changed from), and revert as many as we need. Complexity amortizes out. (We can't revert more changes than there have been). For example, a snippet from malcolm's code: |
|
0
Oh right. I thought you meant you had general breaking cases for hashing solutions since you seemed so happy when you mentioned them (":D"), which seemed pretty unbelievable to me. |
|
+15
A simpler deterministic solution for Div 1 D is to simply merge children with the same letter, so that every node has at most one child of each letter. We can do this recursively and since each node can get merged at most once, the complexity amortizes out. |
|
0
Actually Xellos mentioned that before the suffix explanation. "One more or less obvious way is computing hashes of our strings in a DFS and then counting the number of distinct hashes (which is why there are anti-hash tests :D)." Although evidently the "anti-hash tests" weren't so effective. |
|
0
You mistyped the last bracket: "b^{2}{" instead of "b^{2}}". |
|
+15
Could you spoil the tedious solution? There is at least I_love_Hoang_Yen, darkshadows and me that would like to know. |
|
-10
O.o? Why does while(hi-lo > 1e-9) break? Does it time out? |
|
+46
Yandex competing with Codeforces for "Most Delayed Contest Platform" award. |
|
+8
But 'even' has a very clear mathematical meaning already. If anything, the incorrect interpretation is more valid than the intended interpretation. |
|
+3
So is the online contest an individual contest or team contest? |
|
+4
That doesn't seem correct... Also, the actual time seems to be just 2 hours before SRM 669... |

|
+21
Really sick questions by Lewin. But also, my submissions for D and E don't seem to show up on the scoreboard?... Did I do something wrong? |
|
+6
|
|
+7
Also onsite competitors are, of course, in one location and also we will not be competing directly against them anyway (so why should their rules restrict us when our team members might not be in the same place?). Perhaps it would be best to do what vk cup finals mirror did: "Note that during the round the team is allowed to use only one computer. This means that you may code/use console/succeed in solving problems in any other manner by using only one computer at time. The only thing that is allowed from two computers is reading the statements." |
|
+23
|
|
+8
Of course he's serious, did you look at your own link? Notice how tourist's worst performance ever is 24th and he came 168th this round? |
|
0
Oh good point... for some reason I thought there was a way to view a comment's source code, or at least to copy the comment with latex intact... |
|
+16
I don't want to sound self serving (although I really am), but isn't the solution I presented to A clearly better than the one added to the main post? Perhaps there is a little bit of bias since kpw29 seems to have had the same solution as the one chosen? :P |
|
+29
There is a much simpler solution that also does not encounter overflow problems. Firstly, to find the answer for [l, r], we can find the answer for [1, r] and subtract the answer for [1, l - 1], so we only need to solve the problem for [1, n] and then apply it twice. If q divides p, the answer is 0. Otherwise if p divides q, the answer is Otherwise, observe that
|
 .
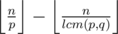 of these.
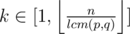 . Additionally,
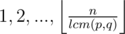 . This is a smaller instance of our original problem so we can recurse on it.
|
+24
Yes. Consider the graph of players where an edge goes from A to B iff A beats B. Now suppose we have some subset of the players such that for every player P in the set and every player S that is not in the set: P beats S or P beats some R that beats S. (Basically, the set must have the property that we can ignore things outside the set, because they will not make anyone inside the set not a winner.) Also, only consider the edges between players in the set (essentially we treat the subset as a smaller version of original problem). Observe that a player P in the set who has a minimal number of incoming edges (remembering to ignore edges to and from players outside of the set), must be a winner. Helpful paint:
Note that any player a in A has at least as many incoming edges as P (since P has a minimal number of edges), so a must be beaten by something in B. Of course, the whole group is a subset fulfilling the requirements so we can simply do this to get our first winner P. Now if the set A of players that beat P is empty, we're done. Otherwise everything in A beats P and A beats everything in B so therefore A is a subset fulfilling the requirements. Thus we can repeat the procedure on A to get our second winner Q. Now if, the set of players in A that also beat Q is not empty, we can recurse again on that set. However, if there is nothing in A that beats Q, we cannot just stop like at the last time (when there was nothing that beat P). Slightly less helpful paint:
Players in B that beat Q are red, players in B that are beaten by Q are green. Alright, now we know that Q beats everything in A, and also beats P, and also beats any green players. Meanwhile, it is also beaten by at least one player in B (since P has a minimal number of incoming edges, and P has an incoming edge from Q, and we just checked that Q has no incoming edges from other players in A, so Q must have at least one incoming edge from B). Therefore, red is a non-empty subset that satisfies the requirements (since everything in red beats Q and Q beats everything else that is not red). So we can recurse on red to find our third winner. Hopefully there isn't a way simpler O(N2) solution that I missed... |


|
+8
I'm curious to know how many people solved problem U (Godzilla and Chess) in O(N2), because both people that I talked to afterwards solved it in O(N3) which I assumed would be too slow. |
|
+19
Here is a solution that doesn't require knowledge of integration (or integration algorithms). Consider the simplified case where we know that, for some interval, every competitor is either before the interval (say there are S of these competitors), after the interval, or somewhere inside the interval with uniform probability over the whole interval (say there are K of these). Then if this arrangement happens, each of the K competitors then has a Note also that if we consider all endpoints together and then take the intervals between consecutive endpoints: then for each interval, every competitor will either not cover that interval at all, or will completely cover that interval (and thus if they are in it, they will have a uniform probability of being anywhere in that interval). Also, there are O(N) of these intervals. This gives us the simple algorithm: for each interval (O(N)), for each competitor i, (O(N)), calculate dp[S][K] = the probability of S other competitors appearing before this interval and K other competitors appearing inside this interval (which we can do in O(N3) with DP). However, this is overall O(N5) which is too slow. So we need to try and calculate "dp[S][K] for all competitors except i", for every i. One idea is to calculate dp[S][K] for all competitors, and then "subtract" each competitor with some maths. Overall this would be O(N4). Theoretically this is possible but in practice it is too inaccurate. Instead we can calculate this with divide and conquer (overall O(N4lgN), or |
 chance to come each of
 buckets
 . For example, for divide and conquer we can calculate
|
0
What? Why should the competition be extended because someone asks for it? Is that not completely unfair to other competitors? |
|
+5
No I think he's saying that asking more than 33 questions gives TLE even though PrinceOfPersia said it gives WA. This guy said the same thing. I'm not sure whether it actually does give TLE but if it does then it is really disappointing since the only clarification than has been answered would have been answered incorrectly. |
|
+22
GG gennady why did I ever doubt you? |
|
+12
|

|
0
The problems didn't all load at the same time for me and I've never used codechef before so I got confused and just clicked the first problem I saw... so I ended up solving Code Land before I realised there were 4 easier problems. I regret everything. |
|
0
... so how long is it? |
|
+2
Now me and jerry can say we solved a problem that YuukaKazami, EvenImage and scott_wu didn't solve. We're at the IOI right now and since we're obviously not good enough to beat them here, this is pretty much the closest thing to an IOI victory as we could have hoped for :D (and also nomnomnom delicious, delicious rating points) |
|
+32
Admitting to rule breaking |
|
0
I reckon it was worth it. |


