



Tips: this is not a normal solution of [problem:2104F], it's just for fun.If you want to know how to normally solve it,please see others solutions. :)↵
↵
My submission:[submission:317717480]↵
↵
Some observations:↵
↵
1. As $n$ increases, the answer is non-decreasing.↵
↵
2. For $n = 999999998$, there are only $568,725$ distinct $S(x)$ values.↵
↵
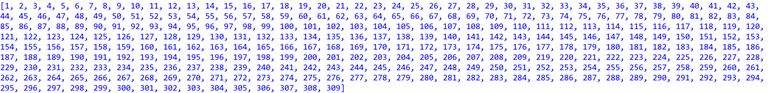
So we can record the positions where new $S(x)$ appears as $x$ increases(call this sequence **A**).Then we can use binary search to find the answer.↵
↵
Here is the top $300$ numbers of **A**↵
↵
↵
↵
But Codefoces's limit of the length of a code if $65535$ characters,and now its too long.(about $5$ MB)↵
↵
We can notice that many of the numbers are continuous increasing(as $1, 2, 3, 4$), so I made another sequence **B** that $B_{i} = A_{i+1} - A_{i}$.↵
And **B** becomes $[1, 1, 1, 1....10, 1, 1, 1...]$. So we can store B as $[[value, count], [value, count]..]$.↵
↵
For example the top $4$ elemnts of **B** are $[1,209],[10,1],[1,90],[10,2]$.↵
↵
Unfortunately, the code is still too long. We need to still work on it.(about 470KB or maybe 200KB, I can't remember the exact size)↵
↵
You can try the previous steps, and surprisingly you will find there is only $122$ different elements in **B**.↵
↵
So we can use $122$ different characters to replace the elements of B,and map them via a dict (C++$unordered_map$).↵
↵
Finally, the size of my solution file becomes 59KB(60k+ characters), and it can be submitted!↵
↵
Here is the generate code(it is used to generate a solution file) :↵
↵
~~~~~↵
import os↵
os.chdir(os.path.dirname(os.path.abspath(__file__)))↵
ans = [0]↵
memo = set()↵
maxn = 10**9 ↵
pre = 0↵
for i in range(1, maxn-1):↵
# find all number i where a new S(i) appear↵
now = "".join(sorted(str(i) + str(i+1)))↵
if now not in memo:↵
ans.append(i-pre) # a[i] - a[i-1]↵
memo.add(now)↵
pre = i↵
ans.append(maxn-pre) # add the last for binary search↵
def zzip(ans):↵
# transform [1,1,1,1,1,1,1,2] into [[1,7],[2,1]]↵
res = [[0, 1]]↵
for i in range(1, len(ans)):↵
if ans[i] != ans[i-1]:↵
res.append([ans[i], 1])↵
else:↵
res[-1][1] += 1↵
return res↵
def chrr(i):↵
#tranform a number into a char↵
if i < 60:↵
ch = chr(i + 32)↵
elif i < 94:↵
ch = chr(i + 33)↵
else:↵
ch = chr(i + 100)↵
return ch↵
def szip(ans):↵
# transform [[1,7],[2,1]] into memo: {'!':[1,7],'"':[2,1]} and s: !"↵
res = []↵
memo = {}↵
memo2 = {}↵
idx = 0↵
for i in ans:↵
if tuple(i) not in memo:↵
memo[tuple(i)] = chrr(idx+1)↵
memo2[chrr(idx+1)] = i↵
idx += 1↵
res.append(memo[tuple(i)])↵
return memo2, "".join(res)↵
memo2, res = szip(zzip(ans))↵
with open("Fgenerated.py", "w", encoding='utf-8') as f: # write into the solution file↵
print("# Generator Author:FZANOTFOUND",file=f)↵
print("s=", "'''",res,"'''", file = f, sep='')↵
print("memo=", str(memo2).replace(": ", ":").replace(", ",","), file=f, sep='')↵
print("""from bisect import bisect_right↵
ans=[0]↵
for i in range(1,len(s)):↵
for _ in range(memo[s[i]][1]):ans.append(ans[-1]+memo[s[i]][0])↵
for _ in range(int(input())):print(bisect_right(ans,int(input()))-1)""", file=f)↵
~~~~~↵
↵
↵
↵
↵
↵
↵
↵
↵
↵
↵
↵
My submission:[submission:317717480]↵
↵
Some observations:↵
↵
1. As $n$ increases, the answer is non-decreasing.↵
↵
2. For $n = 999999998$, there are only $568,725$ distinct $S(x)$ values.↵
↵
So we can record the positions where new $S(x)$ appears as $x$ increases(call this sequence **A**).Then we can use binary search to find the answer.↵
↵
Here is the top $300$ numbers of **A**↵
↵
↵
↵
But Codefoces's limit of the length of a code if $65535$ characters,and now its too long.(about $5$ MB)↵
↵
We can notice that many of the numbers are continuous increasing(as $1, 2, 3, 4$), so I made another sequence **B** that $B_{i} = A_{i+1} - A_{i}$.↵
And **B** becomes $[1, 1, 1, 1....10, 1, 1, 1...]$. So we can store B as $[[value, count], [value, count]..]$.↵
↵
For example the top $4$ elemnts of **B** are $[1,209],[10,1],[1,90],[10,2]$.↵
↵
Unfortunately, the code is still too long. We need to still work on it.(about 470KB or maybe 200KB, I can't remember the exact size)↵
↵
You can try the previous steps, and surprisingly you will find there is only $122$ different elements in **B**.↵
↵
So we can use $122$ different characters to replace the elements of B,and map them via a dict (C++
↵
Finally, the size of my solution file becomes 59KB(60k+ characters), and it can be submitted!↵
↵
Here is the generate code(it is used to generate a solution file) :↵
↵
~~~~~↵
import os↵
os.chdir(os.path.dirname(os.path.abspath(__file__)))↵
ans = [0]↵
memo = set()↵
maxn = 10**9 ↵
pre = 0↵
for i in range(1, maxn-1):↵
# find all number i where a new S(i) appear↵
now = "".join(sorted(str(i) + str(i+1)))↵
if now not in memo:↵
ans.append(i-pre) # a[i] - a[i-1]↵
memo.add(now)↵
pre = i↵
ans.append(maxn-pre) # add the last for binary search↵
def zzip(ans):↵
# transform [1,1,1,1,1,1,1,2] into [[1,7],[2,1]]↵
res = [[0, 1]]↵
for i in range(1, len(ans)):↵
if ans[i] != ans[i-1]:↵
res.append([ans[i], 1])↵
else:↵
res[-1][1] += 1↵
return res↵
def chrr(i):↵
#tranform a number into a char↵
if i < 60:↵
ch = chr(i + 32)↵
elif i < 94:↵
ch = chr(i + 33)↵
else:↵
ch = chr(i + 100)↵
return ch↵
def szip(ans):↵
# transform [[1,7],[2,1]] into memo: {'!':[1,7],'"':[2,1]} and s: !"↵
res = []↵
memo = {}↵
memo2 = {}↵
idx = 0↵
for i in ans:↵
if tuple(i) not in memo:↵
memo[tuple(i)] = chrr(idx+1)↵
memo2[chrr(idx+1)] = i↵
idx += 1↵
res.append(memo[tuple(i)])↵
return memo2, "".join(res)↵
memo2, res = szip(zzip(ans))↵
with open("Fgenerated.py", "w", encoding='utf-8') as f: # write into the solution file↵
print("# Generator Author:FZANOTFOUND",file=f)↵
print("s=", "'''",res,"'''", file = f, sep='')↵
print("memo=", str(memo2).replace(": ", ":").replace(", ",","), file=f, sep='')↵
print("""from bisect import bisect_right↵
ans=[0]↵
for i in range(1,len(s)):↵
for _ in range(memo[s[i]][1]):ans.append(ans[-1]+memo[s[i]][0])↵
for _ in range(int(input())):print(bisect_right(ans,int(input()))-1)""", file=f)↵
~~~~~↵
↵
↵
↵
↵
↵
↵
↵
↵
↵
↵


