


In light of recent events, I think it may be helpful to add a second measurement to problems.
The main issue
Some problems are very "hit or miss" and others are more "standard". Is there a way to quantify this?
The problemsetter's dream
is a problem rated $$$r$$$ such that everyone with rating $$$\ge r$$$ solves it and nobody with rating $$$\lt r$$$ solves it.
Obviously, this could never happen in real life. But we can generalize this idea of a difficulty curve — on the x axis, you'll have the rating, and on the y axis, you'll have the proportion/probability of people at that rating to solve the problem. At $$$r$$$, the value would be 50%.
Here's an example of what a difficulty curve of a 1600-rated problem might look like:
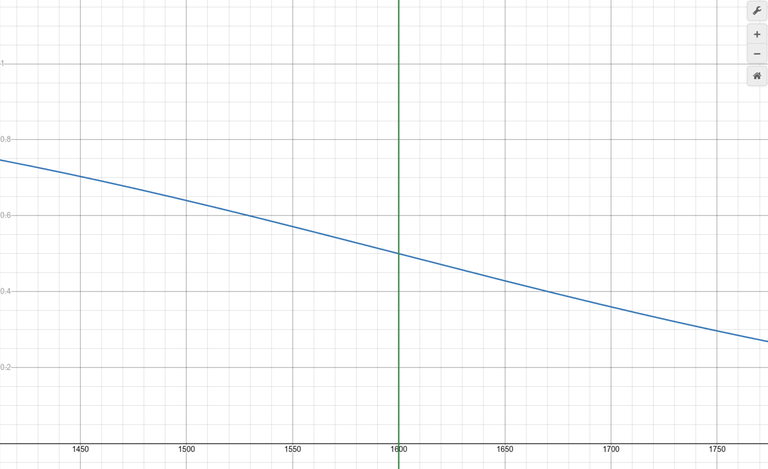
This is the curve of an ideal problem under the Elo model: $$$P(x) = sigmoid(\frac{r-x}{173.7178})$$$ for a problem of rating $$$r$$$ and a person of rating $$$x$$$.
Defining the index
Suppose a person is rated $$$x$$$ and the problem is rated $$$r$$$. This person's contribution to the index would be:
If $$$r \gt x$$$, $$$C = \frac{y-0.5}{E-0.5}$$$, where $$$y$$$ is the 0-1 result and $$$E$$$ is the expected probability calculated using the sigmoid function. If $$$y = E$$$, then the contribution is 1, and if $$$y = 0.5$$$, then the contribution is 0.
If $$$r \lt x$$$, $$$C = \frac{0.5-y}{0.5-E}$$$.
The index of the problem would then be the average of all the contributions. Potentially, we could weight results from low or high rated people slightly heavier, or use a different flavor of average, like mean square or mean exponential.
This would only take O(participants * problems) to calculate for each contest, which is like maybe 10 million cycles worth of CPU time per contest, way less than the amount of work it takes to judge a single submission. Maybe we can even calculate it ourselves with the API, I'm not sure.
The index can be interpreted as:
- Higher than 1: unicorn problem that discriminates even better than what should theoretically be possible under the Elo model
- 1: a perfect problem that discriminates low and high rated people well
- 0 to 1: where most problems are
- 0: a problem that is just a coin flip for everyone and their rating is irrelevant
- Negative: a problem that somehow is easier to solve the lower rated you are
(then, when the index is close to 0, you can cope when you get it wrong by saying it was very hit or miss)


