


This is a blog 5 of a series of blogs about algorithmic challenges I came across when creating tgen.
In this blog we will tackle:
- Generate a skewed connected graph on vertices $$$[0, n)$$$ with $$$m$$$ edges, in $$$\mathcal O(n + m \log n)$$$ time if $$$\mathrm{spread}$$$ is $$$\mathcal O(1)$$$, and in $$$\mathcal O(n \log n + m \log^2 n)$$$ expected time otherwise.
In the previous miniblog we generated a skewed tree with wnext: the parent of $$$i$$$ is wnext(i, e). If $$$e$$$ is small, this is biased toward $$$0$$$ and the tree is star-like; if $$$e$$$ is large, it is biased toward $$$i-1$$$ and the tree is path-like, with endpoints $$$0$$$ and $$$n-1$$$. To get a connected graph with $$$m \ge n-1$$$ edges, the obvious next step is to add $$$m-(n-1)$$$ extra edges uniformly at random. However, if an extra edge connecting the two ends of a long path is chosen, this can collapse the large diameter we are looking for.
Instead, extra edges are ancestor chords of bounded length. After building the same spanning tree as tree::gen_skewed(n, e), an extra edge is a pair $$$(v, u)$$$ where $$$v$$$ is the $$$k$$$-th ancestor of $$$u$$$ for some $$$k \in [2, \min(\mathrm{spread}, \mathrm{depth}(u))]$$$ (length $$$1$$$ is already a tree edge). There are $$$\mathcal O(n \cdot \mathrm{spread})$$$ such chords, and if $$$\mathrm{spread}$$$ is constant, we can list them all and then pick $$$m-(n-1)$$$ of them uniformly.
std::vector<std::pair<int, int>> gen_skewed(int n, int m, int e, int spread) {
	std::vector<int> parent(n), depth(n, 0);
	std::vector<std::pair<int, int>> edges;
	parent[0] = 0;
	for (int i = 1; i < n; i++) {
		parent[i] = wnext(i, e);
		depth[i] = depth[parent[i]] + 1;
		edges.emplace_back(parent[i], i);
	}

	std::vector<std::pair<int, int>> candidates;
	for (int u = 0; u < n; u++) {
		int v = parent[u];
		int max_k = std::min(spread, depth[u]);
		for (int k = 2; k <= max_k; k++) {
			v = parent[v];
			candidates.emplace_back(v, u);
		}
	}

	for (auto [v, u] : choose(candidates, m - (n - 1)))
		edges.emplace_back(v, u);
	return edges;
}
Algorithm 1: skewed connected graph by listing ancestor chords.
Here, choose returns a uniformly random subset of the given size.
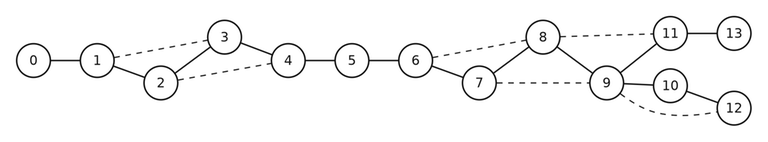
Algorithm 1 with $$$n = 14$$$, $$$m = 19$$$, $$$e = 6$$$, $$$\mathrm{spread} = 2$$$ (path-like). Solid edges are the spanning tree; dashed edges are ancestor chords.
The spanning tree is computed in $$$\mathcal O(n)$$$ time (each wnext is $$$\mathcal O(1)$$$). Inserting $$$m$$$ edges into adjacency sets costs $$$\mathcal O(\log n)$$$ each. If $$$\mathrm{spread}$$$ is $$$\mathcal O(1)$$$, Algorithm 1 runs in $$$\mathcal O(n + m \log n)$$$ time.
If $$$\mathrm{spread}$$$ is large, that list is too big, up to $$$\Theta(n^2)$$$. Interestingly, the same distribution can be sampled without building it, with an extra cost of a logarithmic factor.
Vertex $$$u$$$ has $$$w[u] = \max(0, \min(\mathrm{spread}, \mathrm{depth}(u)) - 1)$$$ ancestor chords. Sample $$$u$$$ with probability proportional to $$$w[u]$$$ by the alias method, sample $$$k$$$ uniformly in $$$[2, \min(\mathrm{spread}, \mathrm{depth}(u))]$$$, and take the $$$k$$$-th ancestor of $$$u$$$ by binary lifting. Repeat until there are $$$m-(n-1)$$$ distinct extra edges.
std::vector<std::pair<int, int>> gen_skewed(int n, int m, int e, int spread) {
	std::vector<int> parent(n), depth(n, 0);
	std::vector<std::pair<int, int>> edges;
	parent[0] = 0;
	for (int i = 1; i < n; i++) {
		parent[i] = wnext(i, e);
		depth[i] = depth[parent[i]] + 1;
		edges.emplace_back(parent[i], i);
	}

	auto up = binary_lifting(parent);

	std::vector<int> w(n);
	for (int u = 0; u < n; u++)
		w[u] = std::max(0, std::min(spread, depth[u]) - 1);

	alias_method a(w);
	std::set<std::pair<int, int>> extra;
	while ((int)extra.size() < m - (n - 1)) {
		int u = next(a);
		int k = next(2, std::min(spread, depth[u]));
		extra.emplace(ancestor(up, u, k), u);
	}
	for (auto [v, u] : extra)
		edges.emplace_back(v, u);
	return edges;
}
Algorithm 2: the same extra edges, without listing the candidates.
Theorem 1: Algorithm 2 has the same extra-edge distribution as Algorithm 1. Algorithm 1 runs in $$$\mathcal O(n + m \log n)$$$ time if $$$\mathrm{spread}$$$ is $$$\mathcal O(1)$$$. Algorithm 2 runs in $$$\mathcal O(n \log n + m \log^2 n)$$$ expected time.
Proof: Let $$$W = \sum_u w[u]$$$ be the number of candidate chords, and write $$$k_{\max}(u) = \min(\mathrm{spread}, \mathrm{depth}(u))$$$. Each candidate is a unique pair $$$(u, k)$$$ with $$$k \in [2, k_{\max}(u)]$$$, so $$$w[u] = \max(0, k_{\max}(u) - 1)$$$. Algorithm 2 samples $$$u$$$ with probability $$$w[u]/W$$$ and then $$$k$$$ uniformly in $$$[2, k_{\max}(u)]$$$, hence each pair $$$(u, k)$$$ has probability
Sampling distinct values uniformly with rejection yields a uniformly random subset of the given size, matching choose in Algorithm 1. (Vertices with $$$w[u] = 0$$$ are never returned by the alias method.)
The lifting table is $$$\mathcal O(n \log n)$$$, and the alias table is $$$\mathcal O(n)$$$. One uniform chord is generated in $$$T = \mathcal O(\log n)$$$ time (via binary lifting). Generating $$$r$$$ distinct values from a uniform sampler that takes $$$\mathcal O(T)$$$ time takes $$$\mathcal O(r(T \log r + \log^2 r))$$$ expected time, by the distinct-generation argument of miniblog 1. Here $$$r \le m$$$ extra edges, so this is $$$\mathcal O(m \log^2 n)$$$ expected.
$$$\square$$$
References
Random trees (miniblog 4): https://codeforces.me/blog/entry/156658
Alias method (miniblog 3): https://codeforces.me/blog/entry/156111
Distinct generation (miniblog 1): https://codeforces.me/blog/entry/154593
Level ancestor / binary lifting (Wikipedia): https://en.wikipedia.org/wiki/Level_ancestor_problem


 Комментарии (0)


