


Problem
Initially, we have an empty multiset $$$S$$$. We need to process $$$q$$$ queries.
Each query is one of the following two types:
- Type 1 —
1 x: Insert the integer $$$x$$$ into $$$S$$$. - Type 2 —
2 u v: Count the number of elements in $$$S$$$ whose values lie in the interval $$$[u,v]$$$.
Limitation : $$$1 \leq x, u, v \leq 10^{9}$$$.
If all queries are known in advance, we can compress all the values and use a standard segment tree to process the updates and queries.
So, what if we have to process the queries online, updating the data structure and answering each query immediately ? Can we still use a segment tree ?
The Idea
Let $$$n$$$ denote the upper bound of the value range. In this problem, $$$n = 10^{9}$$$.
A normal segment tree cannot be built when the value range is as large as $$$10^9$$$ or $$$10^{18}$$$.
However, we do not actually need to create every node. For each update, we only need the nodes on the path from the root to the value $$$x$$$. Therefore, we can create nodes dynamically as they are needed.
This gives us a Dynamic Segment Tree: the tree represents the entire range $$$[1,n]$$$, but only the necessary parts are actually stored.
The key idea is simple:
Build only the nodes that we visit.
Since the height of the tree is $$$O(\log n)$$$, each update creates at most $$$O(\log n)$$$ nodes, while each range query can also be answered in $$$O(\log n)$$$ time.
Here is an example showing the connection between this algorithm and a Trie:
Consider a Dynamic Segment Tree with the entire range $$$[0,15]$$$. Now, suppose we insert two values $$$5$$$ and $$$13$$$, whose binary representation are $$$(0101)_2$$$ and $$$(1101)_2$$$.
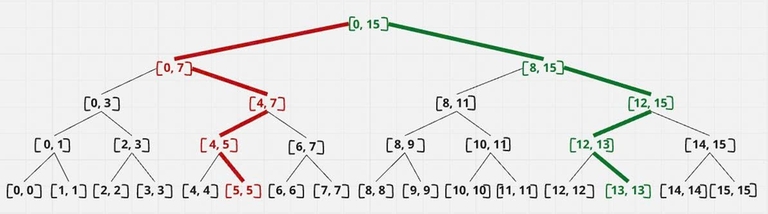
Going to the left child corresponds to a bit of $$$0$$$, while going to the right child corresponds to a bit of $$$1$$$, just like traversing in a Trie.
The implementation
Initially, the segment tree contains only its root. We represent it as $$$(s = 1, l = 1, r = n)$$$, where:
- $$$s$$$ is the node ID.
- $$$[l, r]$$$ is the interval managed by this node.
For each node, we store three pieces of informations:
- $$$Left_s$$$: The left-child ID of node $$$s$$$ (equal to $$$0$$$ if it does not exist).
- $$$Right_s$$$: The right-child ID of node $$$s$$$ (equal to $$$0$$$ if it does not exist).
- $$$Count_s$$$: The number of elements in the multiset whose values lie in the interval $$$[l, r]$$$ of node $$$s$$$.
Update
To insert a value $$$x$$$, we start from the root and recursively move down the tree.
If the current node does not exist, we create it. Then, we increase $$$Count_s$$$ by $$$1$$$, since the value $$$x$$$ belongs to this node's interval.
If $$$l = r$$$, we have reached the leaf corresponding to $$$x$$$ and can stop.
Otherwise, we split $$$[l,r]$$$ at $$$mid$$$: - If $$$x \le mid$$$, we recursively update the left child. - Otherwise, we recursively update the right child.
Notice that we only create nodes along the path from the root to $$$x$$$. Therefore, each update creates at most $$$O(\log n)$$$ new nodes.
void update(int &s, int l, int r, int x){
	if (!s) s = ++NumNode;
	Count[s]++;

	if (l == r) return;

	int mid = l + r >> 1;
	if (mid >= x) update(Left[s], l, mid, x);
	else update(Right[s], mid + 1, r, x);
}
Answer queries
To answer a query $$$[u,v]$$$, we recursively traverse the tree and only consider nodes whose intervals intersect with $$$[u,v]$$$.
There are three cases:
- If the current node does not exist, or its interval is completely outside $$$[u,v]$$$, it contributes nothing, so we return $$$0$$$.
- If the current node's interval is completely inside $$$[u,v]$$$, we can directly return $$$Count_s$$$ without going deeper.
- Otherwise, the interval partially overlaps with $$$[u,v]$$$, so we recursively query both children and sum their results.
Thus, each query takes $$$O(\log n)$$$ time in the usual sparse-tree setting.
int get(int &s, int l, int r, int u, int v){
    if (!s || r < u || l > v) return 0;
    if (u <= l && r <= v) return Count[s];

    int mid = l + r >> 1;
    return get(Left[s], l, mid, u, v) + get(Right[s], mid + 1, r, u, v);
}
Practice Problems
An Advanced Application: 2D Data Structures
Consider an $$$n \times m$$$ matrix $$$a$$$, initially filled with zeros.
We need to process $$$q$$$ queries of the following two types:
- Type 1 —
1 x u y v k: Add $$$k$$$ to every element in the submatrix whose top-left corner is $$$(x,y)$$$ and bottom-right corner is $$$(u,v)$$$:
- Type 2 —
2 x y: Output the current value of $$$a_{x,y}$$$.
Limitation : $$$1 \leq n, m, q \leq 10^{5}$$$.
Solution
The type $$$1$$$ query can be decomposed into two suffix updates:
x n y v ku+1 n y v -k
Therefore, we can use a Fenwick Tree to handle the first dimension. Each Fenwick Tree node stores a Dynamic Segment Tree, which manages the second dimension.
In other words, we have a 2D data structure:
The Fenwick Tree handles the first coordinate, while each Dynamic Segment Tree handles the second coordinate.
Therefore, the total complexity of each update is
For a point query, we similarly visit $$$O(\log n)$$$ Fenwick Tree nodes and perform a query on the corresponding Dynamic Segment Trees. Thus, each query also takes
For memory, each Fenwick Tree update can create at most $$$O(\log m)$$$ new nodes in each of $$$O(\log n)$$$ Fenwick Tree nodes. Therefore, after $$$q$$$ updates, the total memory usage is
Code
const int MAX = 1e5 + 5;

int root[MAX], NumNode = 0;
int Left[MAX], Right[MAX], lazy_add[MAX];

void Update(int &s, int l, int r, int y, int v, int k){
    if (!s) s = ++NumNode;
    if (y <= l && r <= v){
        lazy_add[s] += k;
        return;
    }

    int mid = l + r >> 1;
    if (mid >= y) Update(Left[s], l, mid, y, v, k);
    if (mid < v) Update(Right[s], mid + 1, r, y, v, k);
}

void update(int x, int u, int y, int v, int k){
    for (; x <= n; x += x&-x)
        Update(root[x], 1, m, y, v, k);
    for (u = u + 1; u <= n; u += u&-u)
        Update(root[u], 1, m, y, v, -k);
}

int Get(int &s, int l, int r, int y){
    if (!s) return 0;

    int mid = l + r >> 1;
    if (mid >= y) return lazy_add[s] + Get(Left[s], l, mid, y);
    return lazy_add[s] + Get(Right[s], mid + 1, r, y);
}

int get(int x, int y){
    int ans = 0;
    for (; x; x -= x&-x)
        ans += Get(root[x], 1, m, y);
    return ans;
}


