


For some time, I have been using a specific kind of data structure (I created it while solving a problem without any prior knowledge of the Disjoint Sparse Table). I am pretty sure it is basically a Disjoint Sparse Table, but implemented in a simpler way, so I thought of sharing it.
Prerequisites
The main idea comes from the sliding window technique. Suppose you have q queries where every query has a fixed length (r - l) = k. You can answer each query by combining information from two blocks of size k-1 use the suffix left block and the prefix right block. Then, you can compute the ans using those two values.
Here n = 12, k = 4, and one of the queries is: l = 6, r = 9
So, we create prefix and suffix blocks of size 3. Then, we can computed information from these two blocks to answer the query in O(1).
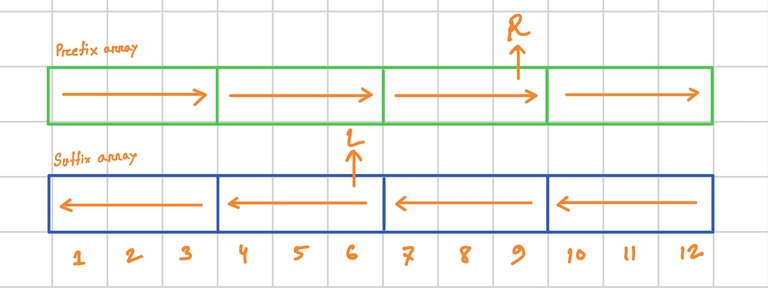
One very important thing to notice here k-1 makes sure that all l, r are in adjacent blocks. So the block size is not the important part, the main point is that l and r have to belong to some adjacent blocks.
DSL like idea:
Build structure:
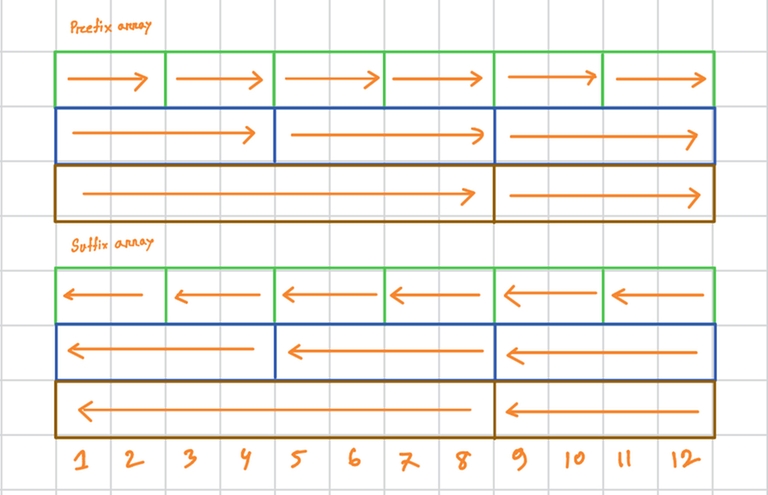
Create suffix and prefix blocks with sizes that are powers of 2, So, have to repeat log(n) times. The memory complexity is also O(2 * n log n), and the time complexity is the same.
For n = 12
Query structure:
For any query l, r, let x = r - l. l and r will always belong to adjacent blocks, where the block size is either the closest power of 2 to <=x or the next larger power of 2.
Example problem and code:
You might need to join the Codeforces group to access this problem


