Скоро Codeforces Round 1133 (Div. 1, Div. 2)! Регистрация здесь. ×

Блог пользователя theoneandonlytron

Автор theoneandonlytron, история, 12 дней назад, По-английски

So this blog won't contain any code, just pure math that I think might help with programming.

  • I would recommend learning math because knowing good math allows you to save A LOT of code.
  • This is my blog to compile what I've learned. I hope that when you read this, you learn something.

Theory

  • Definition: $$$n! = n\cdot(n-1)\cdot(n-2)\cdots1$$$, with $$$0!=1$$$.

  • The number of ways to permute a sequence of $$$n$$$ distinct elements is $$$n!$$$. This can be proven by choosing the first element: we have $$$n$$$ choices for it. Then we have a subproblem of permuting the remaining $$$n-1$$$ elements, so we get $$$n!=n\cdot(n-1)!$$$. Starting with $$$0!=1$$$, this proves the formula for all nonnegative integers $$$n$$$.

  • The number of ways to choose and permute $$$k$$$ elements out of $$$n$$$ distinct elements is $$$\frac{n!}{(n-k)!}$$$. This is simple because we can use the same proof as for $$$n!$$$, but stop after choosing $$$k$$$ elements:

$$$n\cdot(n-1)\cdots(n-k+1)=\frac{n!}{(n-k)!}.$$$
  • The number of ways to pick $$$k$$$ elements out of $$$n$$$ distinct elements, where order doesn't matter, is $$$\frac{n!}{(n-k)!k!}$$$. This is simple: we start with the number of ways to choose and permute $$$k$$$ elements out of $$$n$$$. Since the same $$$k$$$ elements can be permuted in $$$k!$$$ ways, we divide by $$$k!$$$ so we don't overcount their different orders. We write this as $$$\binom{n}{k}$$$.

  • The number of ways to permute a sequence containing duplicate elements is $$$\frac{n!}{c_1!c_2!c_3!\cdots}$$$, where $$$c_i$$$ stands for the number of occurrences of each distinct element. Why does this work? For each group of identical elements, we could permute them in $$$c_i!$$$ ways, but all these permutations look the same. Therefore, we divide by $$$c_i!$$$ for each group so we don't count duplicates.

Problems

1.

How many distinguishable arrangements are there of 1 brown tile, 1 purple tile, 2 green tiles, and 3 yellow tiles in a row from left to right? Tiles of the same color are indistinguishable.

  • Use the theory for arranging repeated elements that I mentioned above.
$$$\frac{(1+1+2+3)!}{3!\cdot2!}=\frac{7!}{3!\cdot2!}=420.$$$

2.

A child builds towers using identically shaped cubes of different colors. How many different towers with a height of 8 cubes can the child build with 2 red cubes, 3 blue cubes, and 4 green cubes? One cube will be left out.

  • This is simple casework.

  • If a red cube is left out:

$$$\frac{8!}{3!\cdot4!}=280.$$$
  • If a blue cube is left out:
$$$\frac{8!}{2!\cdot2!\cdot4!}=420.$$$
  • If a green cube is left out:
$$$\frac{8!}{2!\cdot3!\cdot3!}=560.$$$
  • The answer is $$$280+420+560=1260$$$ ways.

3.

A license plate in a certain state consists of 4 digits, not necessarily distinct, and 2 letters, also not necessarily distinct. These six characters may appear in any order, except that the two letters must appear next to each other. How many distinct license plates are possible?

  • Consider the choices for the letters and digits.

  • We have 4 digits, and each digit can be anything from 0 to 9.

  • So the number of possibilities for the digits is $$$10^4$$$.

  • For each letter, we have 26 options, so we have $$$26^2$$$ possibilities.

  • The number of positions we can choose for the pair of letters is $$$6-2+1=5$$$, including placing them entirely to the left of the digits.

  • The answer is

$$$10^4\cdot26^2\cdot5=33\,800\,000.$$$

4.

At a gathering of 30 people, there are 20 people who all know each other and 10 people who know no one. People who know each other hug, and people who do not know each other shake hands. How many handshakes occur within the group?

  • The total number of handshakes and hugs is $$$\binom{30}{2}$$$.

  • The number of hugs between people who know each other is $$$\binom{20}{2}$$$.

  • We can calculate the number of handshakes by hand as follows:

$$$\frac{30\cdot29}{2}-\frac{20\cdot19}{2}=15\cdot29-190=435-190=245.$$$

5.

In a table tennis tournament, every participant played every other participant exactly once. Although there were twice as many right-handed players as left-handed players, the number of games won by left-handed players was 40% more than the number of games won by right-handed players. There were no ties and no ambidextrous players. What is the total number of games played?

  • Compared to the previous problem, this problem is more obscure, but we can solve it by putting a limit on what $$$n$$$ can be.

  • Let the number of right-handed players be $$$2n$$$ and the number of left-handed players be $$$n$$$.

  • The ratio of games won by left-handed players to games won by right-handed players is $$$7:5$$$.

  • The total number of games is $$$\binom{3n}{2}$$$.

  • Every game between two right-handed players gives one win to a right-handed player, so we get this inequality:

$$$\frac{5}{12}\binom{3n}{2}\geq\binom{2n}{2}.$$$
$$$2n(2n-1)\leq\frac{5}{12}\cdot3n(3n-1).$$$
$$$24(2n-1)\leq15(3n-1).$$$
$$$48n-24\leq45n-15.$$$
$$$3n\leq9\implies n\leq3.$$$
  • After getting $$$n\leq3$$$, we can test every value in $$${1,2,3}$$$ and find the valid one.

6.

Each square in a $$$3\times3$$$ grid of squares is colored red, white, blue, or green so that every $$$2\times2$$$ square contains one square of each color. How many different colorings are possible?

  • This problem is really great because it involves some casework.

  • At first, it looks really hard, but if you fix one $$$2\times2$$$ square, you can work out the others.

  • Let's say we fix the top-left $$$2\times2$$$ square. We have the following arrangement:

$$$\begin{matrix} A & B & x_1 \\ C & D & x_2 \\ x_5 & x_4 & x_3 \end{matrix}$$$
  • Here, the $$$x_i$$$ represent empty squares, and $$$A,B,C,D$$$ are the four different colors. The number of ways to arrange these colors in the fixed square is $$$4!$$$.

  • Now let's fix the other elements. Consider the pair $$$(x_1,x_2)$$$. We can put either $$$(A,C)$$$ or $$$(C,A)$$$. Let's first put $$$(C,A)$$$.

  • If we put $$$(C,A)$$$, then $$$(x_5,x_4)$$$ must be $$$(A,B)$$$, because choosing $$$(B,A)$$$ would create a duplicate $$$A$$$ in the bottom-right $$$2\times2$$$ square.

  • If we put $$$(A,C)$$$, then either $$$(A,B)$$$ or $$$(B,A)$$$ works for $$$(x_5,x_4)$$$.

  • After fixing $$$x_1,x_2,x_4,x_5$$$, the value of $$$x_3$$$ is automatically fixed.

  • So the number of ways is

$$$4!(2+1)=24\cdot3=72.$$$

7.

Henry's Hamburger Haven offers its hamburgers with the following condiments: ketchup, mustard, mayonnaise, tomato, lettuce, pickles, cheese, and onions. A customer can choose one, two, or three meat patties and any collection of condiments. How many different kinds of hamburgers can be ordered?

  • The number of condiments is 8.

  • The number of patties the customer can choose is in $$${1,2,3}$$$.

  • Each condiment can either be included or left out, so the total number of ways is

$$$2^8\cdot3=768.$$$

8.

How many 15-letter arrangements of 5 A's, 5 B's, and 5 C's have no A's in the first 5 letters, no B's in the next 5 letters, and no C's in the last 5 letters?

  • If we fix two of the three letters, then we can fix the last letter. Let's fix A and C because they are the letters allowed in the middle block.

  • If we fix the arrangement in the middle 5 positions, we can then arrange the remaining letters in the first 5 and last 5 positions.

  • The formula we want is

$$$\sum_{k=0}^{5}\binom{5}{k}^3.$$$
  • Let's explain why. Let $$$k$$$ be the number of A's in the middle 5 positions, where $$$k$$$ goes from 0 to 5.

  • The number of ways to put these A's in the middle is $$$\binom{5}{k}$$$.

  • After putting the A's in the middle, the positions of the C's in the middle are fixed. There are $$$5-k$$$ of them.

  • After that, we must put the remaining $$$k$$$ C's in the first 5 positions, giving $$$\binom{5}{k}$$$ arrangements.

  • We must also put the remaining $$$5-k$$$ A's in the last 5 positions, giving $$$\binom{5}{5-k}$$$ arrangements.

  • All remaining positions are B's.

  • Because $$$\binom{5}{k}=\binom{5}{5-k}$$$ by symmetry, the final formula is

$$$\sum_{k=0}^{5}\binom{5}{k}^3.$$$

9.

Three numbers, $$$a_1,a_2,a_3$$$, are drawn randomly and without replacement from the set $$${1,2,3,\ldots,1000}$$$. Three other numbers, $$$b_1,b_2,b_3$$$, are then drawn randomly and without replacement from the remaining set of 997 numbers.

Let $$$p$$$ be the probability that, after suitable rotation, a brick of dimensions $$$a_1\times a_2\times a_3$$$ can be enclosed in a box of dimensions $$$b_1\times b_2\times b_3$$$, with the sides of the brick parallel to the sides of the box. If $$$p$$$ is written as a fraction in lowest terms, what is the sum of the numerator and denominator?

  • Denote the sets by $$$A={a_1,a_2,a_3}$$$ and $$$B={b_1,b_2,b_3}$$$.

  • Let's consider the set $$${a_1,a_2,a_3,b_1,b_2,b_3}$$$. The number of ways to pick this set is $$$\binom{1000}{6}$$$.

  • Now we just need to count the valid ways to assign the elements of each chosen set to $$$A$$$ and $$$B$$$. Multiplying this by the number of ways to pick the set gives the total number of valid assignments.

  • Name the six elements $$$x_1,x_2,x_3,x_4,x_5,x_6$$$ in increasing order. There are some observations we can make.

  • $$$x_1$$$ must be in set $$$A$$$. If $$$x_1$$$ were in $$$B$$$, it would be smaller than every element in $$$A$$$, so the box could not contain the brick.

  • $$$x_6$$$ must be in set $$$B$$$, because no other element is bigger than $$$x_6$$$.

  • So we have $$${x_2,x_3,x_4,x_5}$$$ left. Now we can try every combination and check whether the sorted dimensions of $$$A$$$ are smaller than the corresponding sorted dimensions of $$$B$$$.

  1. $$$A={x_1,x_2,x_3}$$$, $$$B={x_4,x_5,x_6}$$$: correct.

  2. $$$A={x_1,x_2,x_4}$$$, $$$B={x_3,x_5,x_6}$$$: correct.

  3. $$$A={x_1,x_3,x_4}$$$, $$$B={x_2,x_5,x_6}$$$: correct.

  4. $$$A={x_1,x_2,x_5}$$$, $$$B={x_3,x_4,x_6}$$$: correct.

  5. $$$A={x_1,x_3,x_5}$$$, $$$B={x_2,x_4,x_6}$$$: correct.

  6. $$$A={x_1,x_4,x_5}$$$, $$$B={x_2,x_3,x_6}$$$: incorrect.

  • So there are 5 valid assignments for every set of six elements. There are $$$\binom{6}{3}$$$ equally likely assignments in total, so
$$$p=\frac{5}{\binom{6}{3}}=\frac{5}{20}=\frac14=25\%.$$$

Thank you for reading! I hope you learned something from this blog.

Credit to AMC and Omega Learning for the problems and resources that helped me learn these topics.

Полный текст и комментарии »

  • Проголосовать: нравится
  • -1
  • Проголосовать: не нравится

Автор theoneandonlytron, история, 3 недели назад, По-английски

This blog is for documenting my learning journey in competitive programming. Hope someone enjoys it and finds it helpful for their own learning.

Credit to ChatGPT and Claude for helping me find some great modern 1900 problems.

Theory

  • I would recommend knowing all USACO Guide Gold topics. I think you should know most of them to get to CM, plus some more data structures such as tries and advanced segment tree techniques.

  • To understand this blog, I would recommend completing all USACO Guide Silver topics.

Problem 1: 2174B

  • The problem looks like classical DP, but $$$k$$$ is pretty high. In normal DP, we could do $$$dp[\text{position}][\text{prefix_max}][\text{cost}]$$$ and, for every state, try changing the current element into $$$k$$$ possible values. Total complexity: $$$O(nk^3)$$$.

  • However, this is obviously going to TLE since the number of operations is too high for 2 seconds. So we try to find some observations that lead to a DP optimization.

  1. Consider the optimal array $$$b$$$. If $$$b_i \gt 0$$$, then it should increase the prefix maximum. Otherwise, setting $$$b_i \gt 0$$$ would be suboptimal.

  2. Using the first observation, we can see that the positive values in the optimal array $$$b$$$ would be strictly increasing. We can consider each element's contribution to the total sum as $$$b_i \cdot (\text{distance to the next positive element or the end})$$$.

  • So we want to maximize the contribution. We should make the larger $$$b_i$$$ contribute more? Then it is optimal to put $$$b_i$$$ as far to the left as possible.

  • This means we can store the first position that can hold value $$$i$$$, which removes the position dimension from our DP. Therefore, we can use $$$dp[\text{prefix_max}][\text{cost}]$$$, which helps us AC this problem.

Code: My solution

Problem 2: 2138B

  • When the problem looks weird / ad hoc, the only way is casework :)

INITIAL KNOWLEDGE NEEDED:

  • The minimum number of adjacent swaps needed to sort an array is the number of inversions in the array. Every swap of an adjacent inverted pair changes $$$a_i \gt a_{i+1}$$$ into $$$a_i \lt a_{i+1}$$$, reducing the number of inversions by $$$1$$$.

  • After doing some casework, we can conclude that the array is not perfect if there is a triple $$$a_i \gt a_j \gt a_x$$$, where $$$i \lt j \lt x$$$. Otherwise, it is perfect.

  • Once we get that, the answer is simple: calculate the maximum position $$$i$$$ such that there is a triple ending at $$$i$$$, and for every query, just use a segment tree to get the maximum in $$$[l, r]$$$.

Code: My solution

Problem 3: 2217D

  • This problem was really hard for me to figure out.

  • But the problem can be changed into splitting the array at each $$$p_i$$$, giving segments $$$[p_i, p_{i+1}-1]$$$, along with the first and last segments.

  • Consider a change to be a position where $$$a_i \ne a_{i+1}$$$.

  • We can pair changes from one segment with changes from another segment. This guarantees that one $$$p_i$$$ is between the two segments. Try drawing it out or imagining it.

  • We can keep pairing changes from different segments as long as the largest number of changes in one segment is at most half the total number of changes.

  • Otherwise, we match as many changes as possible with the other segments, then add the remaining changes in the biggest segment.

Code: My solution

Problem 4: 2231D

  • This one is general knowledge of prefix sums + A BUNCH OF CASEWORK.

  • Consider all the cases you need. Debugging skill IS THE MAIN SKILL NEEDED in this problem. If you AC all the sample test cases, then you would AC the tests... probably :)

  • I'm not going into the details for this problem.

Code: My solution

Problem 5: 2246D

  • This problem is game theory. Usually, there is an optimal way for Alice / Bob to defeat the other player, and if you know that optimal strategy, you can find the answer.

  • The optimal strategy for Bob here is really simple.

  • If there is an odd element in array $$$a$$$, he can always swap that odd element into $$$a_2$$$ and force $$$a_1$$$ to become $$$0$$$ through $$$-1$$$ or $$$/2$$$ operations. This turns it into a brute-force problem.

  • So Alice should add to some elements to reduce the number of moves by making all numbers end in $$$X$$$ zeroes in binary. This allows the array to be divided by $$$2$$$ a total of $$$X$$$ times before Bob executes his optimal strategy.

  • For each $$$X$$$, find the cost. But there is a second thing you should debug: what if you could do some more operations on $$$a_i$$$ to reduce the cost even further after dividing by $$$2$$$ a total of $$$X$$$ times? For example, $$$255 \to 256$$$.

  • The extra addition cost would be $$$\text{amount_add} \cdot 2^X$$$. We know that we can reduce the number of moves by at most the bit count of the current number, which would be around $$$20$$$ to $$$30$$$. So just brute force it.

Code: My solution

Problem 6: 2133D

  • This problem looks weird at first, but it's actually still casework. Literally almost every problem :))

  • So let's say we ignore the chain damage thing. What would be the optimal answer without chain damage? Obviously, kill the top one first, then the second, then the third, and so on. The topmost one should be dropped first.

  • Using that idea, when would it be beneficial to use the chain? It would be beneficial when there is a bunch of ones in front of a number. So when should we use the chain, and when should we not? That leads us to DP.

  • We're looping from $$$n-1$$$ down to $$$0$$$ because it is optimal to throw the topmost one first.

Case 1: We just kill mob $$$i$$$ and add $$$dp[i+1]$$$ to the cost.

Case 2: We kill mob $$$i$$$, throwing mob $$$i+1$$$ down and creating a chain reaction. This leads to a few more cases.

Let $$$v$$$ be the first position after $$$i+1$$$ with $$$a_v \gt 1$$$.

Let $$$\text{fallcost}$$$ be the cost of eliminating both $$$a_i$$$ and $$$a_{i+1}$$$.

  • We take $$$\text{fallcost} + dp[v]$$$, making them two separate stacks.

  • We take $$$\text{fallcost} + dp[v-1]$$$, making $$$v$$$ fall.

  • We take $$$\text{fallcost} + \text{cost}[v] - 1 + \text{remaining cost}$$$, adding position $$$v$$$ to the chain fall.

Code: My solution

Problem 7: 2226D

  • Classic ad hoc / casework problem :))

  • Okay, so let's do some casework. Hmm, if I want to sort the array, I should be able to move the smallest element to the left?

  • I can swap adjacent elements if they have different parity.

  • So then I can make all the even elements go to the left and all the odd elements go to the right.

  • Okay, so how do I move the smallest element to the left? Hmm, what if there is a way to create a "reversing device" that allows me to put the elements in order?

  • This gives us an insight: if the smallest and biggest elements have different parity, we can use the previous observation. Move all the elements with even parity after the biggest one to the rightmost side, and all the elements with the smallest element's parity before it to the leftmost side. This makes the biggest and smallest elements touch. Then we can move elements of either parity into this device and swap everything into its correct place.

  • What if the biggest and smallest elements have the same parity? Then we could choose the second biggest, third biggest, fourth biggest...

  • We could also choose the second smallest, third smallest, and so on.

  • So let $$$v$$$ be the smallest value with different parity from the minimum, and let $$$g$$$ be the biggest value with different parity from the maximum.

  • We can always swap elements within $$$[\text{minimum}, g]$$$ and within $$$[v, \text{maximum}]$$$. But we cannot swap an element smaller than $$$v$$$ with an element bigger than $$$g$$$, because that would require an element bigger than $$$g$$$ or smaller than $$$v$$$ with the opposite parity.

  • So just compare the biggest position of an element smaller than $$$v$$$ and the smallest position of an element bigger than $$$g$$$. If they overlap in the wrong order, then it's impossible; otherwise, it's possible.

Code: My solution

Problem 8: 2066B

  • Looks kinda hard, but it's still casework :)))

  • Hmm, okay, what if we think about the MEX of the subsequence we pick? If the MEX is $$$0$$$, then we can pick all elements greater than $$$0$$$.

  • We cannot choose $$$0$$$ twice, because including $$$0$$$ updates the MEX.

  • So the answer must be either the total number of elements greater than $$$0$$$, or that number plus $$$1$$$.

  • Then it's a matter of updating the MEX and checking whether taking all the positive elements plus one $$$0$$$ is valid.

Code: My solution

Thank you for reading!

Полный текст и комментарии »

  • Проголосовать: нравится
  • +46
  • Проголосовать: не нравится

Автор theoneandonlytron, история, 4 недели назад, По-английски

This blog is for compiling my learning and my way of thinking when solving a problem. Some people might benefit from this, so enjoy!

CREDIT TO USACO.GUIDE. THE PROBLEMS ARE FROM THERE. THANK YOU SO MUCH!

Theory

  • Hashing is a way to convert a string/number into a number using the idea of base conversion. For example, $$$10_{10}=1010_2$$$.
  • So we convert a string by mapping each character $$$a,b,c,\ldots,z$$$ to $$$1,2,3,\ldots,26$$$ and treating them as digits in a chosen base.
  • But we take the result modulo $$$\mathrm{Mod}$$$ to make sure the number doesn't explode. This creates a collision probability: two different strings can have the same hash modulo $$$\mathrm{Mod}$$$.

Template

const ll Mod = 1000000009LL;
const ll Base = 271LL;

struct hashed_string{
    private:
    string s; ll n;
    vector <ll> prefix;
    vector <ll> pow;
    public:
    hashed_string(string a){
        s = a; n = a.size();
        prefix.assign(n, 0);
        ll sum = 0;
        pow.assign(n+1, 0);
        pow[0] = 1;
        for (int i = 1; i <= n; i++){
            pow[i] = (pow[i-1] * Base) % Mod;
        }
        for (int i = 0; i < n; i++){
            prefix[i] = ((sum * Base) % Mod + s[i] - 'a' + 1) % Mod;
            sum = prefix[i];
        }
    }
    ll get_hash(ll l, ll r){
        ll x = prefix[r];
        if (l >= 1){
            l--;
            x = ((x - prefix[l] * pow[r - l] % Mod) % Mod + Mod) % Mod;
        }
        return x;
    }
};

Big Hash + Random Base

  • To make the hash harder to hack, we can use a big mod and choose a random base each time the program runs.
  • Here, $$$\mathrm{Mod}=10^{18}+3$$$, which is prime. But now multiplying two numbers can overflow a long long, so we use __int128 before taking the modulo.
  • The base is generated once and shared by all hashed strings, so we can still compare their hashes, RANDOM THE MOD OUT OF LIST IF DOING IT IN CF.
  • This makes fixed anti-hash tests much harder to use, but collisions are still possible.
  • Use this instead of the template above. get_hash(l,r) still uses 0-based, inclusive indices, and the character mapping is for lowercase a to z.
#include <bits/stdc++.h>
using namespace std;
using ll = long long int;

const ll Mod = 1'000'000'000'000'000'003LL;
mt19937_64 rng(chrono::steady_clock::now().time_since_epoch().count());
const ll Base = uniform_int_distribution<ll>(257, Mod - 2)(rng);

ll mul(ll a, ll b){
    return (__int128)a * b % Mod;
}

struct hashed_string{
    private:
    string s; ll n;
    vector <ll> prefix;
    vector <ll> pow;
    public:
    hashed_string(string a){
        s = a; n = a.size();
        prefix.assign(n, 0);
        ll sum = 0;
        pow.assign(n+1, 0);
        pow[0] = 1;
        for (int i = 1; i <= n; i++){
            pow[i] = mul(pow[i-1], Base);
        }
        for (int i = 0; i < n; i++){
            prefix[i] = (mul(sum, Base) + s[i] - 'a' + 1) % Mod;
            sum = prefix[i];
        }
    }
    ll get_hash(ll l, ll r){
        ll x = prefix[r];
        if (l >= 1){
            l--;
            x = (x - mul(prefix[l], pow[r - l]) + Mod) % Mod;
        }
        return x;
    }
};

Problem List

Problem 1

Problem

  • This problem is template hashing. The complexity comes from $$$\frac{N}{1}+\frac{N}{2}+\frac{N}{3}+\cdots$$$, which is around $$$O(N\log N)$$$.
  • For every possible period length $$$i$$$, compare each full segment $$$[j,j+i-1]$$$ with the segment $$$[0,i-1]$$$.
  • Then compare the leftover suffix with the part of the prefix that has the same length.

Code

Problem 2

Problem

  • This problem is great because you can't just delete a phrase and forget about it. Deleting a phrase might create a new censored phrase.
  • So we can find an intuition like this: if I delete the phrase $$$[i,j]$$$, the two segments before and after it join together and might create a new censored word.
  • We can change the template from taking a string in its initialization to starting with an empty string and allowing characters to be added one by one.
  • The new censored word must be around the place where we deleted the previous word. So we add characters one by one until the ending equals the censored word, delete that suffix, and keep going.
  • We also remove the corresponding prefix hashes when we delete characters.

Code

Problem 3

Problem

  • This problem is template hashing + an optimization trick.
  • Consider the counts of $$$0$$$ and $$$1$$$. We can brute force the replacement length of the symbol with the larger count.
  • This works because $$$\max(\mathrm{cnt}[0],\mathrm{cnt}[1])\ge\left\lceil\frac{|s|}{2}\right\rceil$$$, where $$$|s|$$$ is the length of the pattern.
  • So there are only around $$$O\left(\frac{|t|}{|s|}\right)$$$ lengths to try. For each one, we calculate the other length and check the whole pattern in $$$O(|s|)$$$ using hashing. Therefore, the total is $$$O(|t|)$$$ after preprocessing.
  • Remember that the two replacement strings must be nonempty and different.

Code

Problem 4

Problem

  • Some people hash the strings and consider all permutations, but I do bitmask DP (simpler ngl).
  • So the way to do this problem is to consider all pairs $$$(i,j)$$$ where string $$$i$$$ is put after string $$$j$$$. We consider how much of the suffix of $$$j$$$ overlaps with the prefix of $$$i$$$.
  • If $$$i$$$ is a substring of $$$j$$$, then we shouldn't consider $$$i$$$ at all. For equal strings, keep only one.
  • Then do bitmask DP: $$$dp[\mathrm{mask}][i]$$$ represents the minimum length after putting the strings in $$$\mathrm{mask}$$$ into one string and ending with string $$$i$$$.
  • We only need to consider the last string because we have already removed the situation where one string is contained in another.

Code

Problem 5

Problem

  • This problem uses binary search on the length and an $$$O(NM)$$$ check, so the total complexity is $$$O(NM\log M)$$$.
  • The problem uses template hashing, so no need to explain the template again.

Code

Problem 6

Problem

  • This problem is simulation from each position. We hash the angles and the distances, then take the minimum extra distance she needs.
  • Encode straight movement, left turns, and right turns as different values. For example, straight movement $$$\to 1$$$, a $$$90^\circ$$$ corner $$$\to 2$$$, and a $$$270^\circ$$$ corner $$$\to 3$$$.
  • To handle the angles, I used vectors (there is probably better code).

Code

Problem 7

Problem

  • This problem is really interesting, and the clue is pretty hard to find.
  • At first, if we brute force every pair of strings $$$(i,j)$$$ and find the cost, the complexity would be $$$O(N^2K)$$$, which would TLE if $$$N$$$ is big. So what if we could guarantee that we only use this approach when $$$N$$$ is small?
  • That brings us to an insight like sqrt decomposition: if $$$N$$$ is big, we use $$$O(NK^2)$$$; otherwise, we use $$$O(N^2K)$$$.
  • So we choose the smaller one, giving $$$O(NK\min(N,K))$$$. With $$$NK\le 3\cdot10^4$$$, the maximum amount of work is around $$$3\cdot10^4\sqrt{3\cdot10^4} \lt 6\cdot10^6$$$ operations.
  • If $$$N$$$ is small, we brute force as above.
  • If $$$K$$$ is small, we consider every pair of positions $$$(i,j)$$$ with $$$i \lt j$$$. These are the positions where two strings might differ.
  • We delete positions $$$i$$$ and $$$j$$$ by merging the hashes of $$$[0,i-1]$$$, $$$[i+1,j-1]$$$, and $$$[j+1,K-1]$$$, treating empty ranges as empty strings.
  • For every string, we check whether any pair $$$(i,j)$$$ gives the same remaining hash as another string. If it does, the two strings differ in at most $$$2$$$ positions.

Code

Problem 8

Problem

  • This problem is misleading at first. The problem states CYCLIC SHIFT OF ROWS AND COLUMNS, which means shift all rows by $$$x$$$, then shift all columns by $$$y$$$. You choose $$$(x,y)$$$.
  • So we can convert the problem like this: if we create a copy of the block and put it to the right of the original, we can generate all blocks after shifting the rows.
  • Then we do that again downward to generate all blocks after shifting the columns.
  • So the problem is converted to finding the lexicographically smallest $$$n\times m$$$ submatrix in the big matrix.
  • We use 2D hashing: hash each row, then use the adding-hashes idea from the USACO problem to create a vertical prefix hash of the row hashes.
  • Then we consider each position $$$(i,j)$$$ as the top-left corner. We use binary search to find the first row where two candidates differ, then the first character in that row, and keep the smaller one.

Code

Problem 9

Problem

  • This problem seems pretty hard at first, but the key is $$$X\le 30$$$, so there might be a solution with around $$$NX$$$ states or something like that.
  • Second, we see that the split sausage is a subsequence, not necessarily one continuous substring.
  • This means that once we consider a substring as a part of the split sausage, we don't really care about the earlier positions anymore. We only need to know how much of the target prefix they have covered.
  • So we can use DP to track the maximum position we have covered after using $$$j$$$ pieces: $$$dp[i][j]$$$.
  • For every position $$$i$$$, let $$$p=dp[i][j]$$$. We just need to find the first position where the suffixes $$$t[p\ldots m-1]$$$ and $$$s[i\ldots n-1]$$$ differ, using hashing and binary search.
  • If they match for $$$L$$$ characters, update $$$dp[i+L][j+1]$$$ with $$$p+L$$$. We can also skip the current position.

Code

Problem 10

Problem

  • This problem seems impossible at first, but the trick is pretty clever.
  • When we consider each sequence $$$i$$$, we can calculate the total cost, but that doesn't really prove anything. A distance of $$$k-1$$$ and another distance of $$$k+1$$$ still add up to $$$2k$$$.
  • So is there a way that the total cost can tell us whether it's valid?
  • This brings us to the ingenious solution of assigning each sequence a random number.
  • Let the random number for sequence $$$j$$$ be $$$w_j$$$, and let $$$W=\sum_j w_j$$$. If $$$d(i,j)$$$ is the distance between sequences $$$i$$$ and $$$j$$$, we check whether $$$\sum_j w_jd(i,j)=k(W-w_i)$$$.
  • If all the distances are $$$k$$$, this always works. If they aren't, the random numbers make it unlikely that the differences cancel out.

Code

Extension: XOR Equality

Theory

  • If we assign each unique value a random hash, we can take the XOR of all the unique values' hashes in a vector.
  • Then we can compare $$$\mathrm{set}(x)=\mathrm{set}(y)$$$ in $$$O(1)$$$ using their maintained hashes, with a small collision probability.
  • The important part is taking each unique value once, because repeated copies can cancel out under XOR.

Problem 11

Problem

  • To count how many subarrays $$$[l,r]$$$ are valid, we can convert the problem into comparing the prefix states at $$$r$$$ and $$$l-1$$$.
  • For this problem, we need to track each value's count modulo $$$3$$$. So we extend the hashing idea to a base-$$$3$$$ state instead of using ordinary XOR.
  • If $$$H_r=H_{l-1}$$$, then every value's frequency in the subarray is divisible by $$$3$$$, assuming no hash collision.
  • But what if a value appears a multiple of $$$3$$$ times, like $$$6$$$ or $$$9$$$, instead of exactly $$$3$$$?
  • For each new occurrence, we can store the minimum position that $$$l-1$$$ is allowed to have. This ensures that no value appears more than $$$3$$$ times.
  • So with both conditions together, each value appears either $$$0$$$ or exactly $$$3$$$ times.

Code

Thank you for reading!

Полный текст и комментарии »

  • Проголосовать: нравится
  • +44
  • Проголосовать: не нравится

Автор theoneandonlytron, история, 5 недель назад, По-английски

This blog is my personal reflection on what I have learned in Trie

Thank you to anyone help created the problem

Thank you to anyone reading

Thank for Codeforces support

Note

Problem that mention Standard / Easy means repeating ideas.

Theory

  • Trie is used for string searching and searching using a limited amount of character each time.
  • Basically, if for every position you could have x number, you can use Trie to store the answ so it is very powerful.

Template

struct Trie{
    struct Node{
        bool end;
        Node* children[26];
        Node(){
            end = false;
            for (int i = 0; i < 26; i++){
                children[i] = nullptr;
            }
        }
    };
    Node* root;
    Trie(){
        root = new Node();
    }
    void add(string s){
        int p = 0;
        Node* cur = root;
        while (p < s.size()){
            int mychar = s[p] - '0';
            if (cur->children[mychar] == nullptr){
                cur->children[mychar] = new Node();
            }
            cur = cur->children[mychar];
            p++;
        }
        cur->end = true;
    }
    bool find(string s){
        int p = 0;
        Node* cur = root;
        while (p < s.size()){
            int mychar = s[p] - '0';
            if (cur->children[mychar] == nullptr){
                return false;
            }
            cur = cur->children[mychar];
            p++;
        }
        return (cur->end);
    }
};

NOTE

  • BECAREFUL OF TRIE, IT WILL MLE IF YOU DONT MANAGE THE MEMORY RIGHT.

Explanation

  • Everytime you add a string, for every position if the character Node has been created then you just go that node otherwise create a new one and do the same thing.
  • For the find, just go do the same thing as add, and in the end check if there is a string ending there.

Problems that I have done

Problem explanation

PHONELIST

  • For every string check if there is any node moving out of that node they are in, if there is then its NO, otherwise YES.

WORD COMBINATIONS

  • For this problem just do normal dp[i] when dp[i] represent amount of ways to build the string from 0 -> i.
  • For every i run j : i -> n - 1; if string (i..j) is a valid string then dp[j] += dp[i - 1] or 1 if i == 0.

Vasiliy's Multiset

  • For this problem just create a idk chatgpt called it a dynamic Trie.

  • To handle max XOR different we give the following function.

  • Struct node: each node must have 2 children, a running_count, a count amount of number ending and value of this Node.

  • decompose(x): convert a number into base 2 when a[0] == biggest bit and a[31] = smallest bit.

  • add(x): do just like template but for each position running_sum += delta, at the end, cnt += delta.

  • find(x): At every step, do the following:

  • if there is a number ending here, take max(x ^ val);
  • if children[current_bit ^ 1] is avaliable go there;
  • otherwise go to the children[current_bit].

A Lot of Games

  • This problem we're going to perfom dfs on Trie.
  • Make a normal Trie but include each node the following: bool dp[2].
  • dp[0] represent can lose, dp[1] represent can win.
  • Lets do a dfs: if we say this Node can win, then there must be a children node that cannot win and the same for lose.
  • At the end we are going to have a certain can_win and can_lose combination for the root.
  • We do casework below:

  • if Root.can_win = false, then the Second person always win;
  • if Root_canwin = true and canlose = true, then the first person can force losing until last round and win the last round, First person win;
  • if Root_canwin = true and Root_canlose = false, the answer would be k % 2, explanation:
    • if the Winning person know that they can force the losing person on the losing person's turn to win so the parity stays the same;
    • The winning person could force the win which allow the winning person to keep the parity.

Sausage Maximization

  • The idea of this problem is still dynamic trie like 3rd problem, for every prefix, create a trie containing a bunch of suffixes and 0, and find max(query of prefix[i], suffix[i]) over all i.

Xor Subsequence (Hard Version)

  • Amazing problem, seems impossible at first because we need to store 2 queries at the same time which I believe would be impossible (my opinion).
  • But lets consider the following, at position i is the position where abp+1 ^ bp > abp ^ bp+1, we can fix all the other one to be equal which means that:
  • The fix positions would be abp+1 ^ bp+1, from 0 -> i - 1, and then for positon we do the following casework:
  • Let fix_bit = abp+1 ^ bp+1; call bit_node = bit of abp+1 at pos i, and bit_index = bit of bp+1 at pos i.
  • If bit_node == bit_index:

  • if bit_node == bit_index == 1, we need a abp where pos i = abp = 0 and bp = 1;
  • if bit_node == bit_index == 0, abp = 1 and bp = 0 (in pos i).
  • If bit_node != bit_index:

  • if bit_node == 1 then we need abp = 0 and bp = 0;
  • if bit_index == 0 then we need abp = 1 and bp = 1.
  • So we just add to the Struct of Node a dp[2] to it to store the above parameters and we just go to each position, query lis every time, find max, LIS[i] = query_answ + 1, and then update Trie again.

Yasya and the Mysterious Tree

  • Pretty good problem, My solution might not be as neat as the other ones.
  • So we can do the following, store the path from u -> root (root = 1) in the trie and every query, we just need to query path from v -> root ^ x ^ max query(of u -> root) so the part from lca(u,v) gonna cancel out.
  • To keep this use a dynamic trie and 2 trie to keep one that is static trie and ones not, because if depth[node] % 2 == 0 then u -> root nots gonna change on query 1 and but if its == 2 then its gonna change.
  • So store one that is static ones not and find the answer each time.

Additional Pratice

Полный текст и комментарии »

  • Проголосовать: нравится
  • +5
  • Проголосовать: не нравится

Автор theoneandonlytron, история, 5 недель назад, По-английски

This blog is my personal reflection on what I have learned in Dp Digit

Theory

  • Dp digit template is something like this:
ll dfs(pos, tight, [some conditions], target)
    if pos == target:
        return something

    if (current_state != -1) return current_state
    limit = if tight = true --> target[pos] else 9 (may vary depending on problem)

    for i : 0 --> limit:
        update_tight()
        answ += do something()

    dp[pos][tight][some condition] = answ
    return answ

Trick

$$$\text{Answ}(L,R)=\text{Answ}(0,R)-\text{Answ}(0,L)$$$
  1. If you dp digit allow the numbers to move around, fix the segment l - r its goona be in making it much easier

Ideas

Gym 100886 G

  • this problem mentioned max, which mean you can't use trick 1
  • so we must keep a low_tight for keeping the number >= L, and a high_tight to keep a number <= R
  • and then you just keep max number for each state simple
  • Be careful on the limit because you might be off by one

SPOJ PR003004

  • This problem is a little bit complicated, because we must store (current sum, total number)
  • Formula:
$$$ \text{answ.sum} += i \cdot \text{total\_number} + \text{current\_sum} $$$
$$$ \text{answ.number} += \text{total\_number} $$$

Codeforces 1036C

  • Chill problem standard easy

Codeforces 628D

  • Problem require 2 requirment:
  • A mutiple of M
  • appear D ONLY ON even position
  • for the mod requirement just store mod of M very simple

  • The even requirement is a bit hard but it is possible, just store the current parity of the position (stays odd until started)

CSES 2220

  • standard no comment

CodeChef DGTCNT

  • Not really dp digit because contain a lot of combinatorics but it contain dp digit idea
  • so first we have a bunch of requiremnt, which require:
$$$ cnt[0] = a_0 \text{ OR } cnt[1] = a_1 \text{ OR } \dots \text{ OR } cnt[9] = a_9 $$$
  • This is clear inclusion exclusion. So we must run through every mask (complexity
$$$2^{10}$$$

) - the idea for this problem is to walk on tight - the moment tight turn off it never turns on again which mean the moment the tight turn off we use combinatorics to count (ways to shuffle the numbers in mask * number of ways to shuffle the number not in mask)

  • Precaculate Combinatoric also be careful with 0 it will mess your program up.

Codeforces 1073E

  • standard store mask of all the one that has appeared

USACO 1307

  • very fun problem indeed, instead of normal dp digit, we use the tight logic again
  • consider dp[l][r][cmp] where a segment cover l -> r of digit B
  • why can we do this? : Because when fix the position we add the number to then the number wont get moved and we dont need to worry about position anymore (**GREAT TRICK**)

  • so now we can consider the boolean expression when add a_i to left or right of a segment l - r
  • consider a general formula

  • function g(x,y) definition: (this function is used in order to mark the number much easier)

if (x > y) return 2;
if (x == y) return 1;
if (x < y) return 0;
  • function f(x,y) definition: (this function is used to merge to cmp toghether):
if (x == 0 or (x == 1 and y == 0)) return 0;
if (y == 1 && x == 1) return 1;
else return 2;
  • So for every number we add into this each segment and max using thif function formula, and update dp[l][r][mask]
  • So the answer after is dp[0][n-1][mask : 0 -> 1] + every lower segment starting at 0
  • the segment must start at 0 because when we update we add to every dp[i][i][comp(current number, target[i])], so therefore there would be at least 1 copy at every position i

USACO 1115

  • Ideas Look Horrifying at first with the weird formula but we can rephrase the ugly formula using this
  • THe formula means that every position in two number x_i and y_i in base-3 must have same parity
  • we can rewrite (x_i, y_i) as (x_i, x_i + some number)
  • Note this work because if (x_i, y_i) is on then (y_i, x_i) would also be on
  • when we addition on bit, the bit[x] must not be equal to base, if the bit[x] == 0 then every number would work
  • when we consider bit[x] of the SomeNumber part in (x_i, x_i + some number), if after we add all the smaller bit, the current:
$$$ (\text{bit}[x] + \text{carryover}) \bmod 3 \ne 0 $$$

we can fix the number and continue on with the addition so the problem become much more simpler

  • the problem now become, given L - R find L <= x <= R where x has some position equal to the position we just fixed above

Thank you to anyone help created the problem Thank you to anyone reading Thank for codeforces support Note : Problem that mention Standard / Easy means repeating ideas.

Полный текст и комментарии »

  • Проголосовать: нравится
  • +19
  • Проголосовать: не нравится

Автор theoneandonlytron, история, 6 недель назад, По-английски

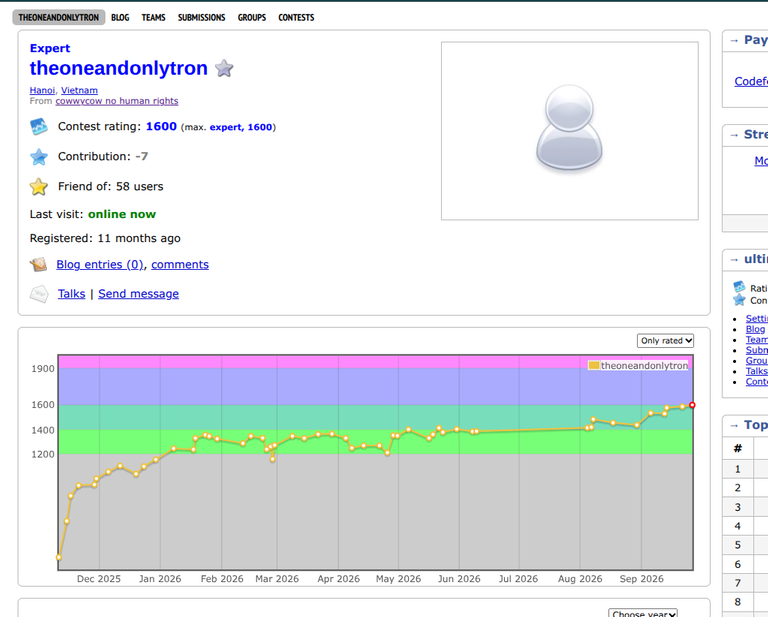
Thanks so much for anyone that has supported me in that time, thank you so much Also for anyone don't know algorithm that I learned before expert include: - Bsearch, prefix sum, brute force (including recursion) - dfs, bfs, Dijkstra, dsu, hld, centroid decomposition, virtual tree, mst, topo sort - dsa : Fenwick, segment - eulor tour lca - Hasing (imma learn more), meet in the middle - dp: on trees, sos, bit mask, knapsack, dnc, reroot, digit - tricks : convex hull, alien - small to large merging - meet in the middle - and I think some more minors one

But yez so when I connect the hld, centroid, dnc stuff to my lower bit mask and knapsack stuff imma hit cm trust

image

Update

Полный текст и комментарии »

  • Проголосовать: нравится
  • +43
  • Проголосовать: не нравится