t3jtex's blog

By t3jtex, 3 weeks ago, In English

In this blog I'll cover all the intuition you need for range queries, deriving segment trees, sparse tables and sqrt decomposition. This however is not a blog explaining how to implement segment trees, sparse tables and sqrt decomposition. If you want to learn any specific algorithm from those; this blog is not for you.

What are range queries

Let's say we have an array $$$a$$$ with $$$n$$$ elements. Now we want to make a function getsum(l, r), which returns the sum of elements of this array, from the index $$$l$$$ to $$$r$$$ inclusive. For example for

$$$a = [1, 2, 3, 4, 1, 5]$$$

getsum(0, 3) should return $$$1+2+3+4 = 10$$$. This problem can be easily solved using prefix sums ( I assume you know what prefix sums are, if not, read this first ). What if however we need to implement a second function set(i, x), which should set the $$$i$$$th element to $$$x$$$?

The simplest solution would be:

getsum(l, r) := iterate from l to r summing the numbers in a
set(i, x)    := set the ith number to x

This is $$$O(1)$$$ for set and $$$O(n)$$$ for getsum.

If we use prefix sums however we could make it:

getsum(l, r) := find the sum of [l, r] using prefix sums
set(i, x)    := set the ith number to x, and recalculate the prefix array

Now this is $$$O(n)$$$ for set and $$$O(1)$$$ for getsum.

So how can we make it faster?

Splitting into subsegments

Well let's start from the simple solution, and let's add a second array $$$b$$$. Now the array $$$b$$$ will have $$$\frac{n}{2}$$$ elements, and $$$b_i = a_{2i} + a_{2i+1}$$$. So the array $$$b$$$ will contain the sums of the $$$\frac{n}{2}$$$ subsegments of $$$a$$$ which have length two. So in our starting example we would have:

$$$a=[1, 2, 3, 4, 1, 5] \\ b= [3 \ (1+2), 7\ (3+4), 6 \ (1+5)] $$$

Now how does it help us? When we get a set query, we will just update the value of $$$a_i$$$ and $$$b_{\lfloor \frac{i}{2} \rfloor}$$$, and for a getsum query, we will find all the subsegments in $$$b$$$ that cover our range, and then only if something is left, add it from the $$$a$$$ array.

For example:
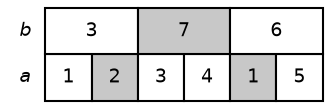
getsum(1, 4) = b[1] (2..3) (only full subsegment in our range) + a[1] + a[4]
set(1, 4)    = b[0] += 4 - a[1] (1/2 = 0)
               a[1] = 4

The time complexity of this solution is still $$$O(1)$$$ for set and $$$O(n)$$$ for getsum. But if we look at the number of numbers we need to sum/change, in set it goes from $$$1$$$ to $$$2$$$ (we need to update two numbers instead of one), and for getsum it goes from $$$r-l+1$$$ to $$$\frac{r-l+1}{2}+2$$$ (instead of summing the whole segment, we sum the segments in $$$b$$$ and then there are at most $$$2$$$ left in $$$a$$$).

Sqrt decomposition
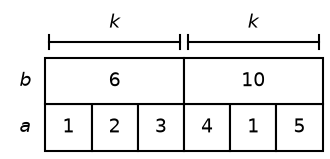
Now this idea allows us to make a better algorithm: Sqrt decomposition. To do it, we start by changing the definition of $$$b$$$. The choice of length equal two, is arbitrary, and we can represent the length by some variable $$$k$$$. Now $$$b$$$ will have length $$$\frac{n}{k}$$$. Let's analyze the time complexity:

Since we still only update two numbers (one in $$$a$$$ and one in $$$b$$$) we get $$$O(1)$$$ for set, but in getsum, we will now sum $$$\frac{r - l + 1}{k} + 2 \cdot (k - 1)$$$ numbers. That is because there will be $$$\frac{r - l + 1}{k}$$$ blocks from $$$b$$$ used and at the end we will need at most $$$2 \cdot (k - 1)$$$ from $$$a$$$. This simplifies to $$$O(\frac{n}{k} + k)$$$ worst case and is minimized for $$$k = \sqrt{n}$$$ (proof is left as an exercise for the reader). So getsum becomes $$$O(\sqrt{n})$$$, which is much better than $$$O(n)$$$.

Now after reading this blog, before moving onto the next part, try to implement both of those algorithms!

Next blog soon (about segment trees).

Full text and comments »

  • Vote: I like it
  • +13
  • Vote: I do not like it

By t3jtex, 4 months ago, In English

Everyday, when i see the recent actions, there is at least one "cheaters found in round xxx". A lot of those "cheaters" found, aren't cheaters and they just use longer variable names, many includes, or std::.

"I WOULD NEVER WRITE A VARIABLE NAME THIS LONG" — i think you never used VS Code's or any other IDE's feature of "autocomplete". "HE USED #include <vector> INSTEAD OF bits/stdc++.h" — macos, msvc. "HE USED std::" — jiangly uses std::, and many people new to codeforces also. "HE WRITES COMMENTS" — greateric.

There are a lot of other pointless arguments people tell all the time and the number of false positives is increasing. Random people looking for cheaters doesnt make sense because:

  • a cheater can just ask AI to give the idea, and he implements it
  • a cheater can just edit the code to make it look less AI
  • instead of wasting your time reading random submissions, you could be doing problems and improve

So please, stop making "cheater found" blogs, as it discourages new people to join codeforces, makes the recent actions tab worse and most people just dont care, and would prefer to read more educational blogs.

Full text and comments »

  • Vote: I like it
  • +138
  • Vote: I do not like it

By t3jtex, 8 months ago, In English

UPD: REGISTRATION IS NOW OPEN

Hello Codeforces,

We invite you to the CodeSquare Round 1, which will take place on Mar/22/2026 17:35 (Moscow time). You will be given $$$6 - 7$$$ problems to solve, and $$$3$$$ hours to solve them. The format will be ICPC, identical to Educational, Div. 4 and Div. 3 rounds. This round is open to all participants.

We'd like to thank:


Note from AlexandruINV (Admin):

It’s genuinely great to see this idea come to life. What started as a simple thought, just a small group of people solving problems together, has already turned into something much more meaningful. Seeing people participate, improve, and engage with each other makes it all worth it.

The Codeforces contest we’re running reflects exactly what I hoped this community could become. I want to thank everyone who helped organize it and supported the idea from the beginning, this wouldn’t have been possible without you.

We’re looking forward to growing this further and making it better over time. Any feedback, suggestions, or ideas for improvement are always appreciated.

I hope you enjoy the problems, and I’m really glad to have this community together.

GLHF!

Full text and comments »

  • Vote: I like it
  • +68
  • Vote: I do not like it

By t3jtex, history, 9 months ago, In English

668948A - Square Root

Solution
Code

668948B - Rectangle

Solution
Code

668948C - Common Prime Factor

Solution
Code

668948D - xyab

Solution
Code

668948E - Coins

Solution
Code

668948F - f(x)

Solution
Code

Full text and comments »

  • Vote: I like it
  • +2
  • Vote: I do not like it

By t3jtex, 9 months ago, In English

Hello Codeforces,

I invite you to the First Codeforces Newbie Round which will take place on Feb/03/2026 22:03 (Moscow time). You will be given 5 — 7 problems to solve, and 2 hours to solve them. The format will be identical to Div. 4 and Div. 3 rounds.

The problems are authored by t3jtex.

I'd like to thank:

Tom_a and Alosza for testing

GLHF

Full text and comments »

  • Vote: I like it
  • +14
  • Vote: I do not like it

By t3jtex, 10 months ago, In English

Quaternary Lifting

In a lot of problems with trees we want to quickly access the $$$k$$$-th ancestor of a node. This is usually done with binary lifting in $$$O(\log N)$$$ time complexity. In normal binary lifting we precompute

$$$\text{jmp}[i][k]$$$ = the vertex we end up after jumping $$$2^k$$$ times from $$$i$$$

However there is a way to half the memory usage — Quaternary lifting ( idk if that is the real name ). In quaternary lifting

$$$\text{jmp}[i][k]$$$ = the vertex we end up after jumping $$$4^k$$$ times from $$$i$$$

In binary lifting we represent the number that represents how many times we want to jump in base-2 and in quaternary lifting we represent it in base-4.

Example

Suppose we want to jump 9 steps from vertex v.

Base-4 representation of 9: $$$21 = 2 \cdot 4^1 + 1 \cdot 4^0$$$

Jump process:

Jump $$$4^1$$$ twice ($$$\text{jmp}[v][1]$$$ 2 times)

Jump $$$4^0$$$ once ($$$\text{jmp}[v][0]$$$ one time)

This shows that if in base-4 a digit is $$$ \gt 1$$$ we perform multiple jumps at the same height.

Why is it useful?

Quaternary lifting has

Space = $$$N \log_4 N$$$ = $$$N \frac{\log_2 N}{\log_2 4}$$$ = $$$\frac{1}{2} N \log_2 N$$$. So it uses 2 times less memory than normal binary lifting!

Implementation

But there is a way to do binary lifting in $$$O(N)$$$ memory — Binary Lifting, No Memory Wasted

Full text and comments »

  • Vote: I like it
  • -7
  • Vote: I do not like it

By t3jtex, 10 months ago, In English

idk if there are any good testers, so i made my own.

Stress testing:

tosts stress \
   --number 1000 \
   --timelimit 100 \
   ./gen \
   ./sol1 \
   ./sol2

Running on pregenerated tests:

tosts run \
   --in-dir tests/in \
   --out-dir tests/out \
   --in-ext in \
   --out-ext out \
   --timelimit 100 \
   ./sol

Generating tests:

tosts generate \
   --in-dir tests/in \
   --out-dir tests/out \
   --in-ext in \
   --out-ext out \
   --number 1000 \
   ./gen \
   ./sol

https://github.com/Tejtex/tosts2

https://crates.io/crates/tosts

Installation:

cargo install tosts

Full text and comments »

  • Vote: I like it
  • +2
  • Vote: I do not like it