


→ Обратите внимание
→ Лидеры (рейтинг)
| № | Пользователь | Рейтинг |
|---|---|---|
| 1 | Benq | 3676 |
| 2 | Kevin114514 | 3659 |
| 3 | jiangly | 3640 |
| 4 | turmax | 3450 |
| 5 | tourist | 3408 |
| 6 | strapple | 3360 |
| 7 | Um_nik | 3354 |
| 8 | squareOf105 | 3348 |
| 9 | maroonrk | 3312 |
| 10 | idontwannadothis…e | 3191 |
| Страны | Города | Организации | Всё → |
→ Лидеры (вклад)
| № | Пользователь | Вклад |
|---|---|---|
| 1 | Qingyu | 153 |
| 2 | nik_exists | 151 |
| 3 | maroonrk | 150 |
| 4 | maspy | 149 |
| 5 | AmShZ | 146 |
| 6 | Um_nik | 143 |
| 7 | Errichto | 139 |
| 8 | adamant | 135 |
| 9 | BledDest | 134 |
| 10 | cry | 130 |
→ Найти пользователя
→ Прямой эфир


Codeforces (c) Copyright 2010-2026 Михаил Мирзаянов
Соревнования по программированию 2.0
Время на сервере: 20.11.2026 05:26:08 (h1).
Десктопная версия, переключиться на мобильную.
При поддержке


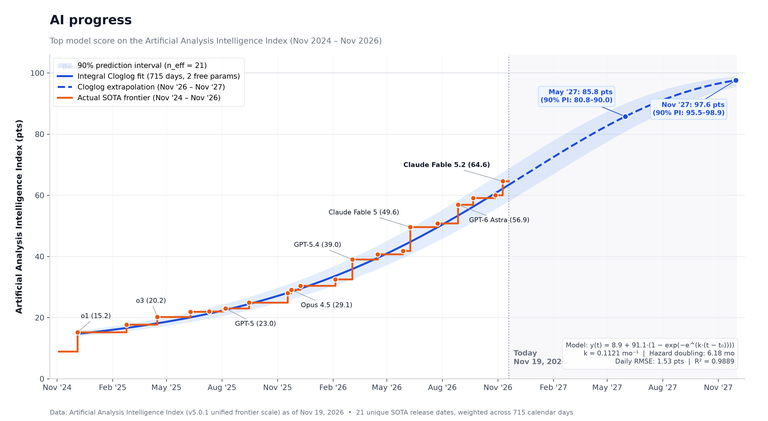
While AI progress is indeed staggering, AA is one of the worst metrics to extrapolate upon/draw conclusions from, and your use of it just exposes the larp.
Can you share a better metric?
I will recalculate
ECI, while also imperfect, is better. Labs have started sharing numbers on internal benchmarks (which are likely more meaningful) but there aren't enough datapoints for these to confidently extrapolate from.
Do Not Reproduce
dw im a stone cold truecel
To be honest, I am just so disappointed with GPT 6.2 that I decide to use Gemini instead.