


Author: TheScrasse
Preparation: TheScrasse
Each value $$$x$$$ is independent of the others; only its own frequency matters.
In a balanced array, value $$$x$$$ must appear either $$$0$$$ times or exactly $$$x$$$ times.
- Each value $$$x$$$ is independent of the others; only its own frequency matters. In particular, for each value, find its frequency $$$f[x]$$$.
- In a balanced array, value $$$x$$$ must appear either $$$0$$$ times or exactly $$$x$$$ times. Specifically, if it appears $$$ \lt x$$$ times at the beginning, you have to delete all its occurrences, otherwise you should keep $$$x$$$ occurrences. Specifically, for each $$$x$$$, add $$$f[x]$$$ to the answer if $$$f[x] \lt x$$$, else add $$$f[x] - x$$$.
Complexity: $$$O(n)$$$ time. Slower solutions (e.g., $$$O(n^2)$$$) are allowed.
Author: TheScrasse
Preparation: TheScrasse
The order of operations does not matter. Only the number of $$$\texttt{4}s$$$ and $$$\texttt{8}s$$$ in the substring matters.
The black cells are the positions we can reach starting from $$$(0, 0)$$$, if we can move orthogonally (using a $$$\texttt{4}$$$) and diagonally (using an $$$\texttt{8}$$$).
A move with an $$$\texttt{8}$$$ is equivalent to two moves with a $$$\texttt{4}$$$, in different directions.
- The order of operations does not matter. So count the number of $$$\texttt{4}s$$$ and $$$\texttt{8}s$$$, and assume there are $$$a$$$ $$$\texttt{4}$$$s and $$$b$$$ $$$\texttt{8}s$$$.
- The grid is symmetrical. We can assume $$$x, y \geq 0$$$ (by making $$$x := |x|$$$, $$$y := |y|$$$).
- The black cells are the positions we can reach starting from $$$(0, 0)$$$, if we can move orthogonally (using a $$$\texttt{4}$$$) and diagonally (using an $$$\texttt{8}$$$).
- In particular, since $$$x, y \geq 0$$$, a $$$\texttt{4}$$$ is a step either up or right while an $$$\texttt{8}$$$ consists of two steps, one up and one right.
- So you make $$$a+2b$$$ steps in total, and only $$$a+b$$$ of them can be in the same direction.
- The necessary and sufficient conditions are
-
- $$$a+2b \geq x+y$$$ (you need to be able to perform $$$x+y$$$ steps, either up or right, to reach $$$(x, y)$$$);
-
- $$$a+b \geq \max(x, y)$$$ (you need to be able to perform $$$y$$$ steps up and $$$x$$$ steps right).
Author: TheScrasse
Preparation: TheScrasse
For each element, determine whether it belongs to a $$$\texttt{MEX}$$$ constraint, a $$$\min$$$ constraint, both, or none.
If an element belongs to both a $$$\texttt{MEX}$$$ constraint and a $$$\min$$$ constraint, it is useless for both constraints.
If an element only belongs to a $$$\min$$$ constraint, you can set it to $$$k$$$ for convenience.
What's the "fastest" way to satisfy a $$$\texttt{MEX}$$$ constraint? What about several constraints simultaneously?
For each element, determine whether it belongs to a $$$\texttt{MEX}$$$ constraint, a $$$\min$$$ constraint, both, or none.
- If an element is covered by a $$$\min$$$ constraint, it must be $$$\geq k$$$, and ideally it should be $$$= k$$$ (so that the constraint is immediately satisfied).
- If an element is covered by a $$$\texttt{MEX}$$$ constraint, it must be $$$\neq k$$$, and ideally it should be $$$ \lt k$$$ (to make the constraint easier to satisfy).
Then
- If an element is not covered by any constraints, it does not matter, and you can set it to any value.
- If an element belongs to both a $$$\texttt{MEX}$$$ constraint and a $$$\min$$$ constraint, it is useless for both constraints, but you must set it to something both $$$\neq k$$$ and $$$\geq k$$$. For example, you can set it to $$$k+1$$$.
- If an element only belongs to a $$$\min$$$ constraint, it is optimal to set it to $$$k$$$.
- The remaining elements are the ones which are only covered by a $$$\texttt{MEX}$$$ constraint. In order to be satisfied, a $$$\texttt{MEX}$$$ constraint must contain at least $$$k$$$ such elements (because it must contain all the elements between $$$0$$$ and $$$k-1$$$, which would violate a $$$\min$$$ constraint). In particular, assigning $$$i \text{ mod } k$$$ at the $$$i$$$-th such element works (if a $$$\texttt{MEX}$$$ constraint contains $$$k$$$ such elements, their values are $$$[0, 1, \ldots, k-1]$$$, possibly shifted).
Complexity: $$$O(nq)$$$ or $$$O(n+q)$$$ per test case.
Bonus: in the above solution, we assign $$$i \text{ mod } k$$$ to the $$$i$$$-th element only covered by $$$\texttt{MEX}$$$ constraints. However, assigning $$$a_i = i \text{ mod } k$$$ to such elements (where $$$i$$$ is the position in the whole array, instead of the position only considering such elements) also works. Can you prove it?
Author: TheScrasse
Preparation: TheScrasse
The worst case is either $$$x = l$$$ or $$$x = r$$$. So you can assume that $$$x$$$ is either $$$l$$$ or $$$r$$$, but you don't know which one.
There exists an optimal strategy where a prefix of offers (after sorting) is accepted using the third option, and a suffix of elements is accepted using the second option.
There exists an optimal strategy where (in addition to the previous properties) at most one offer is rejected.
The worst case is either $$$x = l$$$ or $$$x = r$$$.
Sketch of proof. After fixing the strategy, the number of coins as a function of $$$x$$$ is a straight line.
Then, in order to test a strategy, it is enough to evaluate it at $$$x = l$$$ and $$$x = r$$$ and pick the minimum.
There exists an optimal strategy where a prefix of elements (after sorting) is red, and a suffix of elements is blue.
Sketch of proof. Use exchange argument. For example, if $$$y \leq z$$$, $$$y$$$ is white and $$$z$$$ is red, then we get $$$x-z$$$ coins. If we make $$$y$$$ red and $$$z$$$ white, we make $$$x-y$$$ coins instead.
There exists an optimal strategy where (in addition to the previous properties) at most one element is white.
Sketch of proof. If $$$x \leq y$$$, and they are both white, we can make $$$x$$$ red and $$$y$$$ blue instead.
- Try all possibilities for the white element. So there are $$$O(n)$$$ candidate strategies.
- We can test a strategy in $$$O(1)$$$: find the number of coins as a function of $$$x$$$ using prefix sums, and evaluate it in $$$l$$$ and $$$r$$$ to check the actual worst case.
Complexity: $$$O(n \log n)$$$
Author: TheScrasse
Preparation: TheScrasse
The order of the elements does not matter.
Solve the problem with $$$k = 1$$$.
Iterate over elements from right to left and find their final value if $$$k = 1$$$.
Find the value of each element over time. Can you calculate the value of some element after a fixed number $$$m$$$ of operations?
Binary search the answer.
The order of the elements does not matter. So let's sort the elements in increasing order. Also, we have the freedom to choose the tiebreaker rule (i.e., which elements are increased by $$$1$$$).
- Assume the process stops when all the elements are distinct (i.e., $$$k = 1$$$). Let's find the configuration $$$b_1, b_2, \ldots, b_n$$$ at that point. If some elements are equal, the rightmost does not increase.
- From right to left, if the initial value is $$$a_i$$$, then $$$b_i$$$ is the smallest $$$x \geq a_i$$$ not present in $$$b$$$ yet.
- If we look at a single element over time, it has values $$$a_i, a_i + 1, \ldots, b_i, b_i, \ldots, b_i$$$.
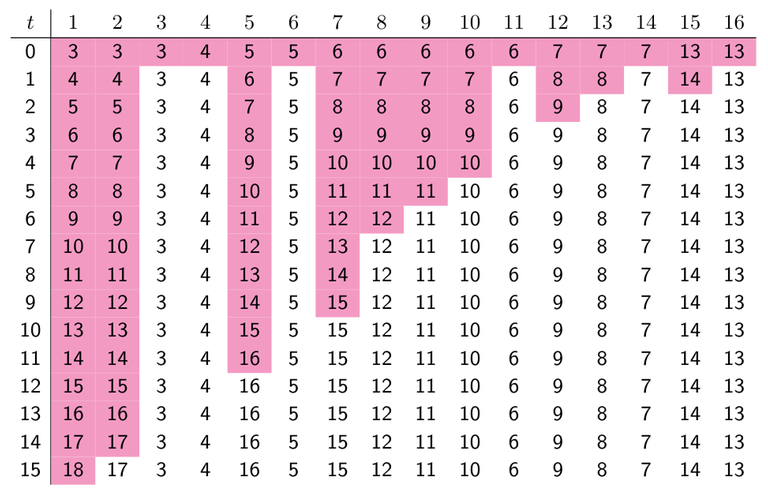
- The maximum number of occurences of one element does not increase after one operation (if value $$$x$$$ appeared $$$\leq k$$$ times, it produces $$$\leq k-1$$$ copies of $$$x+1$$$, and at most one other copy of $$$x+1$$$ survives).
- So we can binary search the answer. Using the process described earlier, we can retrieve the configuration after $$$m$$$ moves in $$$O(n)$$$.
Complexity: $$$O(n \log n)$$$ time (there also exist "magical" $$$O(n)$$$ solutions!)
Author: TheScrasse
Preparation: TheScrasse
How would you write the checker for this problem? (How to check efficiently whether a submission gets AC or WA)?
After you choose $$$y$$$, calculating the optimal $$$l$$$ is easy. From now, let's denote the operations only using $$$y$$$.
Consider some naive strategies: for example, $$$[1, 2, \ldots, n-1]$$$, or $$$[n-1, n-2, \ldots, 1]$$$. Why are they bad? How to improve them?
You can fix your skill modulo $$$2$$$, then modulo $$$4$$$, then modulo $$$8$$$, etc., but that's still a bit too inefficient.
Try with a different modulo.
As a warm-up, think about how we would write the checker for this problem.
We can store the set of all the possible skills (initially, all integers in $$$[1, n]$$$), and perform operations in $$$O(1)$$$ (we have to remove $$$y$$$ and insert $$$y+l$$$).
As a consequence, the optimal value of $$$l$$$ is the smallest one such that $$$y+l$$$ is already in the set. Since we know how to determine the optimal $$$l$$$ for a fixed $$$y$$$, let's denote the operations only using $$$y$$$.
- Naive strategy 1: use operations $$$1, 2, \ldots, n-1$$$. Unfortunately, they are too "increasing".
- Naive strategy 2: use operations $$$n-1, n-2, \ldots, 1$$$. Unfortunately, they are too long.
Better strategy:
- Fix our skill modulo $$$2$$$ using operations $$$n-1, n-3, n-5, \ldots$$$
- Fix our skill modulo $$$4$$$ using operations $$$n-2, n-6, n-10, \ldots$$$
- $$$\ldots$$$
The cost is $$$O(n \log n)$$$ ($$$\approx \log_2 n$$$ layers, $$$O(n)$$$ per layer). We use very few "increasing" operations ($$$1$$$ per layer): we can try to use more (and maybe use less layers).
Generalization:
- Fix our skill modulo $$$3$$$ using operations $$$n-2, n-5, n-8, \ldots, n-1, n-4, n-7, \ldots$$$
- Fix our skill modulo $$$9$$$ using operations $$$n-6, n-18, n-30, \ldots, n-3, n-12, n-21, \ldots$$$
- $$$\ldots$$$
Now we have $$$\approx \log_3 n$$$ layers and $$$2$$$ "increasing" operations per layer.


If we use modulo $$$m$$$, we have $$$\approx \log_m n$$$ layers, each with cost $$$\approx n$$$, and $$$m-1$$$ "increasing" operations per layer, each with cost $$$1000$$$.
We should choose $$$m \approx \sqrt[3]{n}$$$. So the total cost is around
if $n = 250\,000$.
Author: KLPP
Preparation: KLPP
Apply prefix XOR. So, instead of information about $$$a_l \oplus a_{l+1} \oplus \ldots \oplus a_r$$$, assume you can ask information about $$$a_l \oplus a_r$$$.
Find whether the highest bit of every $$$a_i$$$ (viewed as $$$30$$$-bit integer) is $$$0$$$ or $$$1$$$. You can assume that $$$a_1$$$ has highest bit $$$0$$$.
You get two blocks. Recurse.
Solve every block in the most efficient way possible.
Apply prefix XOR. So, instead of information about $$$a_l \oplus a_{l+1} \oplus \ldots \oplus a_r$$$, we assume we can ask information about $$$a_l \oplus a_r$$$.
Let's build a trie containing the $$$a_i$$$. Specifically, each node corresponds to a prefix of the binary representation, and contains positions $$$i$$$ such that $$$a_i$$$ has that prefix. It is not possible to recover the $$$a_i$$$ uniquely, but we can set bits to $$$0$$$ without loss of generality if they do not impact any queries. Then, in order to calculate the answer for some $$$(l, r)$$$, we have to find the LCA of the corresponding nodes.
Suppose we are in some node of the trie containing $$$k$$$ values. We want to recurse into two children, depending on the next bit. This is possible by asking the query.
Specifically, suppose that a node contains positions $$$p_1, p_2, \ldots, p_k$$$. In order to recurse, we need to ask queries between some pairs. We choose this pairs greedily, by calculating a minimum spanning tree (the edges have cost $$$\frac{1}{p_j-p_i+1}$$$). It can be also shown that, in the minimum spanning tree, the picked edges contain either $$$p_1$$$ or $$$p_k$$$, which makes the implementation easier.
Empirically, this solution requires around $$$8$$$ robocoins per test case with $$$n = 100$$$.
Bonus: prove the asymptotic behavior of the solution (idea: for each $$$(i, j)$$$, estimate the probability that the query is performed).
Author: TheScrasse
Preparation: TheScrasse, Dominater069
Start with some "easy" pairs $$$(n, m)$$$. Which ones can you solve?
If you have a solution to $$$(n, m)$$$, can you transform it into a solution to $$$(n+1, m+1)$$$?
If you have a solution to $$$(n, m)$$$, can you transform it into a solution to $$$(n+1, m)$$$?
Find small $$$(n, m)$$$ with at least $$$2000$$$ solutions, and propagate these solutions to some bigger pairs.
Now some pairs are missing. They either have small $$$n$$$, or small $$$n-m$$$.
If $$$n-m$$$ is small, what can you say about the amount of $$$p_i = i$$$?
If $$$n-m$$$ is small, then $$$p_n$$$ must be large.
For convenience, let's find "anti-bitonic" permutations instead (decreasing, then increasing). There is a bijection between bitonic and anti-bitonic permutations.
vector<int> f(vector<int> p) {
    int n = p.size();
    reverse(p.begin(), p.end());
    for (auto &u : p) u = n - u + 1;
    return p;
}
We can transform a solution to $$$(n, m)$$$ into a solution to $$$(n+1, m+1)$$$: just append $$$n+1$$$ at the end.
We can also transform a solution to $$$(n, m)$$$ into a solution to $$$(n+1, m)$$$: append $$$n+1$$$ at the end, and swap $$$p_1$$$ with $$$p_1 + 1$$$.
Let's divide into three cases:
- $$$n \le 18$$$;
- $$$n \ge 19$$$, $$$n - m \ge 10$$$;
- $$$n \ge 19$$$, $$$n - m \le 9$$$.
They can be solved as follows.
- We can find all the anti-bitonic permutations and test them in $$$O(n \cdot 2^n)$$$.
- First, solve $$$(18, i)$$$ for $$$1 \leq i \leq 8$$$ (for each $$$i$$$, we have $$$\geq 2000$$$ solutions). Transform these solutions into solutions to $$$(n, m)$$$.
- $$$p_1, p_2, \ldots, p_n$$$ must have at least $$$n-9$$$ cycles, so it must have at least $$$n-18$$$ fixed points (i.e., $$$p_i = i$$$). The permutation structure is $$$[p_1, \ldots, p_1+1, p_1+2, \ldots, n]$$$: the highlighted square has at most $$$1$$$ fixed point, so there are at most $$$n-p_1+1$$$ fixed points. Therefore, $$$p_1 \leq 19$$$, and we can iterate over all such permutations.

Author: TheScrasse
Full solution: dario2994
Preparation: TheScrasse, Dominater069
Solve the problem with even $$$m$$$.
Solve the problem with $$$t = 1$$$.
For a fixed $$$n$$$, how do "losing" $$$m$$$ look like?
Let $$$(n, l)$$$ ($$$0 \leq m$$$) be losing if you lose if it's your turn, the current integer is $$$n$$$, and you cannot subtract $$$l$$$.
If $$$(n, l)$$$ is losing, then $$$(n+l, l')$$$ with $$$l' \neq l$$$ is winning. This means that the number of losing $$$l$$$ for a fixed $$$n$$$ is either $$$0$$$, $$$1$$$, or $$$m+1$$$. Let's call $$$n$$$ "good", "neutral", and "evil", respectively.
How do the losing states $$$(n, l)$$$ look like?
Our goal is to solve $$$t = 1$$$ in $$$O(n/m)$$$.
How to determine efficiently whether some $$$n$$$ is good or neutral?
In order to determine whether some $$$n$$$ is good or neutral, you can write a recursive function which terminates in $$$O(1)$$$ on average.
Losing positions.
Let $$$(n, l)$$$ ($$$0 \leq m$$$) be losing if you lose if it's your turn, the current integer is $$$n$$$, and you cannot subtract $$$l$$$ (if $$$l$$$ is $$$0$$$, you can subtract everything).
Evil $$$n$$$.
Let $$$n$$$ be evil if $$$(n, 0)$$$ is losing (i.e., you lose even without constraints on the number you subtract).
Bound on the evil $$$n$$$ (I).
There are $$$O(N/m)$$$ evil $$$n$$$. Specifically, let $$$v_1, v_2, \ldots, v_k$$$ be the evil $$$n \leq N$$$. Then, $$$v_i - v_{i-1} \geq m+1$$$ (otherwise you would be able to move from an evil $$$n$$$ to another, contradiction).
Structure of losing positions and solution in $$$O(t(N+m))$$$.
If $$$(n, l)$$$ is losing, then $$$(n+l, l')$$$ with $$$l' \neq l$$$ is winning. This means that the number of losing $$$l$$$ for a fixed $$$n$$$ is either $$$0$$$, $$$1$$$, or $$$m+1$$$. Let's call $$$n$$$ "good", "neutral", and "evil", respectively.
Note that the losing states are $$$O(N+m)$$$ in total.
Even $$$m$$$.
For even $$$m$$$, only the multiples of $$$m+1$$$ are evil. In order to win, you can ensure that the last two moves have sum $$$m+1$$$. Since $$$m+1$$$ is odd, the last move will never be the same as the second last.
From now, let's only consider odd $$$m$$$.
More structure.
Let $$$f(n)$$$ be the distance from the largest evil $$$n' \leq n$$$.
There are three types of losing states.
- $$$(n, l)$$$ with $$$f(n) = 0$$$.
- $$$(n, f(n))$$$.
- $$$(n, f(n)/2)$$$ with $$$f(n) = m+1$$$.
This is a consequence of the slow solution described above. If $$$s$$$ is evil:
- the losing states $$$(s, l)$$$ propagate to $$$n$$$ in $$$[s+1, s+m]$$$;
- only the losing state $$$(s + \frac{m+1}{2}, \frac{m+1}{2})$$$ can propagate to $$$(s+m+1, \frac{m+1}{2})$$$, and in that case $$$s+m+2$$$ is evil.
So $$$s+m+1$$$ cannot be good (it is either neutral or evil).
Bound on the evil $$$n$$$ (II).
Let $$$v_1, v_2, \ldots, v_k$$$ be the evil $$$n \leq N$$$. Then, $$$m+1 \leq v_i - v_{i-1} \leq m+2$$$.

Our goal.
Let $$$v_1, v_2, \ldots, v_k$$$ be the evil $$$n \leq N$$$. We want to find them in $$$O(k) = O(N/m)$$$. In this way, we can solve the problem for all $$$m$$$ in $$$O(\sum_{1 \leq m \leq M} N/m) = O(N \log M)$$$.
Finding $$$v_{i+1}$$$.
We have $$$v_1, v_2, \ldots, v_i$$$, and we want to find $$$v_{i+1}$$$ in $$$O(1)$$$. It is enough to check whether $$$v_i + m + 1$$$ is evil. It's easier to check whether it is not evil, i.e., whether there exists a winning move.
Let's start from some $$$n$$$ which satisfies $$$v_j \leq n \leq v_{j+1}$$$. A winning move must ensure that the opponent cannot move to an evil state (necessary condition). So there are three candidate winning moves.
- Subtracting $$$n-v_j+1$$$ (so that the opponent is too far from $$$v_{j-1}$$$; this can only work if $$$v_j-v_{j-1} = m+2$$$).
- Subtracting $$$\frac{n-v_j}{2}$$$ (so that the opponent would have to subtract $$$\frac{n-v_j}{2}$$$ again to reach $$$v_j$$$).
- Subtracting $$$\frac{n-v_{j-1}}{2}$$$ (so that the opponent would have to subtract $$$\frac{n-v_{j-1}}{2}$$$ again to reach $$$v_{j-1}$$$).
Finding $$$v_{i+1}$$$ efficiently.
The previous observation provides a recursive function which can call itself up to $$$3$$$ times.
The recursive function answers the question "can we win starting from $$$(n, n-v_j)$$$?" (i.e., it is forbidden to make the move which would win immediately). This is equivalent to "is $$$n$$$ good or neutral?"
We want to make the average number of recursive calls less than $$$1$$$, so that the function terminates in $$$O(1)$$$.
- We do not need the first call, because $$$v_{j-1}+m+1$$$ is neutral (proved before).
- The second call happens with probability $$$\lesssim 1/2$$$ ($$$n-v_j$$$ must be even, and the first case must not apply).
- The third call happens with probability $$$\lesssim 3/8$$$ ($$$n-v_{j-1}$$$ must be even, the first case must not apply, and the second call must not succeed).
So the function calls itself $$$\lesssim 7/8$$$ times on average. This is fast enough for all $$$m$$$ (it can be tested locally).


First.
F solution format is broken? last line of it
I don't know how to fix it, the format seems correct but the rendering is broken.
I don't understand why i%k works if i belongs to the MEX category.
Try to come up with a counterexample, and realize it's not possible.
Specifically, this solution seems to break when there are, in this order:
But this means there is a $$$\min$$$ constraint inside a $$$\text{MEX}$$$ constraint, which has no solution anyway, so the input is invalid.
Bouns: solve C with n,k,q<=2e5
i think it is even easier than the original solution
Interesting and thought-provoking problems! I really enjoyed this contest!
This contest might be one of my new favorites, even though Problem D absolutely DEMOLISHED me :3
D involves sorting, so I guess you should mention complexity as nlogn
For E, this my O(n) solution, which isn't magical at all.
Here's a $$$O(n)$$$ solution for E.
Loop backwards from MAX_E (say $$$3N$$$) to $$$1$$$. Let $$$E$$$ be the energy. If $$$cnt[E]$$$ is greater than $$$k$$$, we need to propagate the values to the right. Propagate by incrementing $$$R$$$ repeatedly and doing the following.
- If $$$a[R] = 0$$$, we can drop $$$1$$$ frequency at this index. $$$a[R]$$$ becomes $$$1$$$.
- If $$$a[R] = 1$$$, nothing happens. We pass through.
- If $$$a[R] \gt 1$$$, we take $$$a[R] - 1$$$. $$$a[R]$$$ becomes $$$1$$$.
Stop when we can drop at the current $$$R$$$ safely ($$$cnt + 1 \le k$$$). The answer will be the maximum $$$R - E$$$ across all $$$E$$$ where $$$R$$$ is the ending point. The complexity will be $$$O(n^2)$$$.
To optimize this, use the fact that going over $$$a[i]$$$ where $$$a[i] = 1$$$ does nothing. Maintain a stack by pushing indices where $$$a[i] \neq 1$$$. Instead of incrementing $$$R$$$, we take the next value by popping from the stack. The complexity will be $$$O(n)$$$ which can be proven after doing amortized analysis.
350383732
Although, the solution to F is correct and the margin of error is quite big. I don't think it is a practical approach during the contest.
Instead I used a similar solution that computed the cost of getting all answers to a certain modulo.
So we start with dp[1]=-1000, dp[x]=inf for all other x. The cost of starting position is -1000 as the first transition is discounted.
Then for increasing i,j we compute dp[i*j]=min(dp[i*j],dp[i]+n-n/j+1000*j)
The lowest cost is dp[y], y>=n.
My solution got down to cost of 923188 https://codeforces.me/contest/2157/submission/350336820 What was the lowest cost anyone got?
I got cost of $$$923187$$$ with submission 350386207
I got lower cost of $$$923093$$$ with submission 350386305
That looks like what I have done, but I unnecessarily had
<=instead of<Yeah, just a troll comment
I got a much better result after contest ends, though the ideas are similar.
We need to construct a tree of minimal cost with root $$$n$$$, where the depth of the tree costs $$$1000 \cdot d$$$ and edge $$$(i, j)$$$ costs $$$|j - i|$$$.
A straightforward solution is to construct a chain of length $$$l = \Theta(\sqrt{n})$$$, and the $$$i$$$-th node on the chain is a chain representing a range of length $$$i$$$. This construction gives us a cost of about $$$2n + 1000\sqrt{2n} \approx 1.2 \times 10 ^ 6$$$.
To be simplified, define the tree above as $$$T(i)$$$. Now we construct a chain of length $$$l = \Theta(\sqrt[3]{n})$$$, and the $$$i$$$-th node on the chain has a son of $$$T(i-1)$$$ representing a range. Through this we can achieve a cost of about $$$3n + 1000 \sqrt[3]{3n} \approx 8.5 \times 10^5$$$.
Code: 350368299
You can achieve 855330 and I think that is the optimal value, I'll describe shortly my solution (350461892).
In an optimal solution you should find for each value where to jump to. Then the overall cost is equal to the sum of lengths of the jumps plus 1000 times the longest path. To solve the problem we can minimize for a fixed longest path what is the minimum cost of the jumps using dynamic programming. $$$DP(n, k)$$$ is the minimum cost of the jump (without the cost of the longest path) for $$$n$$$ values and $$$k$$$ longest path. This can be computed in $$$O(n^2 \cdot k)$$$ fixing the smallest number that jumps directly to the end, before that point all path will end at that number and will have length $$$k-1$$$ at most, after that the longest path can have length $$$k$$$. It turns out you can speed up this dp using knuth optimization and compute it in $$$O(n \cdot k)$$$.
Using this approach, and setting $$$k = 73$$$ is enough to solve the problem the cost is $$$998850$$$, setting $$$k = 113$$$ solves the problem with cost $$$855330$$$.
For E, you can just simulate the process in O(n) (this seems to be magic):
For each element of the array count tow often it appears (since the order deosnt matter) Then for each i from 1 to 3*n, let x be how often it appears in the array. If x>k, we set its count to 1 and increase the count of i+1 by x-1. Additionally we can just remember where the process started and this tells us how many operations it took for the array to become ok.
Implementation: https://codeforces.me/contest/2157/submission/350355897
I think I did something somewhat similar as an O(N) solution in python (https://codeforces.me/contest/2157/submission/350347513)
I keep track of consecutive operations needed (operating on 1, 2, 3 etc.) and keep comparing to maxOps and if there's a point where I don't need to operate then I reset ops to 0. In order to simulate this correctly, I have to propagate i+1 to i+2 if needed before I propagate i to i+1. Then when you hit the max freq (plus like 1 or 2) that you could have at the start, then just add that final freq — 1 to your answer so you don't have to simulate to TLE.
I only made my freq array 2*n, but effectively same complexity
why my solution got a WA? I think I share the same thinking with you. ~~~~~ from collections import defaultdict def sol(): n,k=map(int,input().split()) li=list(map(int,input().split())) di=defaultdict(int) for i in li: di[i]+=1 cou=0 for i in range(1,4*n+1): if di[i]>k: di[i+1]+=di[i]-1 cou+=1
for _ in range(int(input())): print(sol()) ~~~~~ [https://codeforces.me/contest/2157/submission/350321034]
I thought I'd misunderstood the problem...In one operation multiple energy level can be adjusted,right?
Yes, you need to maintain where the operation started
I did this. I have no idea why it works. I have vibes, obviously, this is why I implemented it.. but when I think about it in depth, I feel it must be wrong!
Simpler sol'n to D
but this is the simplest:
I don't understand question D, can someone explain the sample test cases pls?
after choosing the equality <= or >= you have to go through each p and then the one giving minimum total score will be your answer.
5 1 10
5 7 3 9 1
in this test case as you have to maximise the total score so you will just assume the p you chose will be on the correct side of inequality
so for p=5 you will get score as 12
The remaining elements are the ones which are only covered by a MEX constraint. In order to be satisfied, a MEX constraint must contain at least k such elements (because it must contain all the elements between 0 and k−1, which would violate a min constraint). In particular, assigning i mod k at the i-th such element works (if a MEX constraint contains k such elements, their values are [0,1,…,k−1], possibly shifted).
I don't understand why i%k works if i belongs to the MEX category.
It is because the elements which are only of type2 would always exist as single continguous strip in an interval (l,r) ,for those i%k would be cyclic anyways.
Problem F was one of the most beautiful problem i have ever solved<3
Hey can you like give a brief idea of how to solve this problem, cause I am not able to understand the editorial of this problem
What is wrong with my solution. The key idea was to decrease one occurrence of each value x, instead of increasing (cnt[x]-1) values by one.
Ah, seeing the solution for B now makes sense.
Damn I was close, shame I was late.
Really enjoyed my first attempt, cheers guys.
If anyone's up for helping, I genuinely do not understand where my solution failed for C: 350330832.
The part where I ran into issues was filling in the mexes, for which I greedily sorted them based on length and filled the free spaces with the remaining missing numbers. For some reason, that was incorrect.
your code returns
0 1 2 3 5 5 0 1 5 5 5 4which the range [5,11] does not have mex 4, since you fill all values in the range [1,6] first causing the range [5,11] to not have enough elements to have mex 4instead of filling k+1 for extra spaces, dont fill in immediately, do it after you fill in 1, 2, ... k-1 for all ranges
Thank you. I also asked some other acquaintances, and they pointed out that mistake as well; however, fixing it alone was not enough, as the sorting logic is still not correct.
Which problem was which at SWERC?
The problem letter at SWERC is the same as the initial letter in the problem name (expect 2157C - Meximum Array 2 which was not at SWERC). Also, in the CF round, 2157B - Expansion Plan 2 was made a bit easier and 2157G - Isaac's Queries was made a bit harder.
You can get the problem PDFs by clicking on the letters at the top of the scoreboard.
"expect",
dont mind this shitposter
my solution to B: 350397978
I came up with this but can't prove why it works. Can someone explain it?
You can actually solve E by just simulating the operations in a smarter way. First, as in the editorial, you see that only the frequencies matter and you can make a priority queue that takes in a struct with 3 parameters: the index, the number of things that have the same value and how many operations it took for the numbers to get to this position ( if you have five 1's, the you can put in the priority queue the triplet {1,4,0} as the numbers are all one, there are 4 of them that need to be moved and they have been moved already 0 times).
Then, the priority_queue should keep the triplets in ascending order, sorted after the first number, the other 2 won't matter as you will see further ( so {3,2,0} is before {4,0,0} and after {2,9,1} ).
Then, you take the first triplet and before you increment the numbers, you see if there are any other pairs that share the first number from the triplet. If this is true, you can simply make one pair instead of the 2, and the resulting pair, if the other 2 are {a,b,c} , {a,d,e} would be {a,b+d,max(c,e)}, because you now have b+d numbers that need to be moved and the number of moves that it would take is just the biggest of the 2.
With this, you can still have a clean nlogn solution.
The code for this part (I know it's not that good, but it works), not in full, but I think you can imagine the rest.
https://codeforces.me/contest/2157/submission/350358558
Can anyone help me in proving the correctness of this solution for today's D? I reached the solution through an observation by plotting on Desmos.
This is a unimodal function, and I solved it using the ternary search method.
Isn't D basically just finding the distance of each number to the median? (https://codeforces.me/contest/2157/submission/350333441)
That's what I did, with the exception that if the median is outside the range of l <= x <= r, then you set this target median as l or r, whichever is closer, since that's the closest value to each value in the array while still being in the possible range.
I guess it's kind of said in the editorial with "The worst case is either x=l or x=r"
can you kindly explain your solution. why did you find the sum of distance of median as answer? thank you
Considering even number of elements ->
Let's say you calculate your ans based on median = ans_med, and claim the offers accordingly. you can see that, no matter what the actual rank P is this ans_med will never change. But if you had claimed any differently, then we set the actually rank P = median to give you newAnswer < ans_med. So whatever you do ans_med is the best choice.
Basically Fix actual rank = median, now if you dont claim based on P = median, then you are obviously getting lower answer. But if you are claiming based on P = median, then even if we change actual rank to anything, the answer remains same. You can visualize this by drawing points on number line. Code — 350640234
Dang... I'm happy I got to the point of F of getting every possible skill to be at n-2, n-4, n-6 etc. then to be at n-4, n-8, n-12 etc. but that ends up being over 2 million cost. Didn't know how to get the right segment length / layer / modulo / power, though I started trying to write a function to minimize.
"magical" O(n) solution for E: 350347721
(translate from chinese by DeepSeek,original chat)
First, the original sequence is not important; we can try to keep only the count of each element (using a frequency array/bucket).
Each operation is equivalent to keeping only 1 instance of a value in the bucket and moving the rest to the next higher value (this process is applied to all values simultaneously).
We discuss the cases for each non-zero value in the bucket, leading to the following two scenarios:
Case 1:
If there are enough "none" (empty) slots below, it will expand into:
Case 2:
Here, before the above bucket meets the condition, it collides with a non-empty position below.
In this case, each downward move reduces the count of the lower element by one, while the upper element remains unchanged, until the lower element is exhausted and the upper elements catch up.
It can be observed that this scenario will eventually cause the lower elements to be "flattened" (though this may occur at different times—for example, the first few moves may flatten the lower part a bit before the upper part catches up). However, the element that takes the most time will always be the one from the upper part.
Therefore, we use a stack to simulate the above two scenarios, maintaining the situation where "pillars" (value counts) are stacked together at the current position. We use a pointer to track the actual position of the top of the stack and simulate the process of this stack of pillars moving downward one step at a time.
a $$$O(n)$$$ solution for E
The statement of E is really terrible.
In problem H, was it known during testing that the most straightforward way of writing a brute force works? Just consider values from $$$1,2,\cdots,n$$$ in order, and decide whether to put each element on the left or right, write a dfs (with minimal pruning) and it passes.
It occured to me after I had submitted that it works because of the intended construction, the first branch tried will be $$$1,?,?,\cdots,?$$$, and the next branch will be $$$2,3,4,?,?,\cdots,?,1$$$.
I tried switching Left->Right to Right->Left and the code immediately gets TLE (xd), maybe it would be better to ask for anti-bitonic permutations after all?
It was not known, there was only 2 tester solutions, both being same as editorial (one of them on their own; one by reading editorial)
I think if one is able to get the vibe that brute force could possibly work in the contest, they should more or less notice similar conclusions as the official solution.
My first thought was the brute force as well, but I doubt whether it could pass. While I was trying to prove it, I noticed that the number of possible permutations surpasses $$$2000$$$ very fast (which is what we hope in order for the brute force to work), and came up with a similar solution as the editorial.
I would say D have have a very simple solution, and its very natural to think that if(a[n/2]>=l && a[n/2]<=r) then we select a[n/2] as p because by median property we can say that sum of absolute difference between all elements and its median is minimum otherwise p = min(a[n/2],r) and p = max(a[n/2],l) and the code is ~~~~~ void solve() { ll n, l, r; cin >> n >> l >> r; vector a(n); repp(i, n) { cin >> a[i]; } sort(all(a)); ll ans = 0; ll median = a[n / 2]; median = max(l, a[n / 2]); median = min(r, median); for (int i = 0; i < n; i++) { ans += abs(a[i] — median); } cout << ans << endl;
} ~~~~~
`
please explain B, i tried to read that and not understandable.
In particular, since x, y >= 0, a 4 is a step either up or right while an 8 consists of two steps, one up and one right. So you make a + 2b steps in total, and only a + b of them can be in the same direction.
https://codeforces.me/contest/2157/submission/350375681
can somebody tell me why my code is not Correct For Problem C
Your solution is similiar to mine. Sort c2 by the default operator
<ofpair<int,int>then you can get AC. I don't know why :(Sorry for my poor English.
Another solution to problem D using the mathematical median
We need to find the maximum possible score you can guarantee, that is, the minimum score we can win if we iterate all possible values of $$$p$$$ over $$$[l,r]$$$.
Let's solve an easier version of a problem with $$$l=1$$$ and $$$r=1e9$$$.
The mathematical median has an exciting property, the minimised absolute deviation property. In other words, for a sorted array $$$a_1,a_2,...,a_n$$$, $$$\sum_{i=1}^{n}|m-a_i|$$$ will be minimized if $$$m=a_\left\lfloor \frac{n}{2} \right\rfloor$$$, the array's median.
The answer would be $$$\sum_{i=1}^{n}|m-a_i|$$$.
Now, let's return to the original problem.
Define $$$m$$$ as the position in $$$[l,r]$$$ where we will win the minimum score. After we sort the array $$$a$$$, we will set the value of $$$m$$$ to be the median of $$$a$$$ if it is in the range $$$[l,r]$$$. Otherwise, $$$m=l$$$ if the median is strictly less than $$$l$$$, and $$$m=r$$$ if the median is strictly greater than $$$r$$$.
The answer would be $$$\sum_{i=1}^{n}|m-a_i|$$$, and the overall complexity is $$$O(nlogn)$$$.
My submission: 350340949
Bonus of G:
In each step we are using approximately a cost of $$$\sum_{i=1}^{100} \frac{1}{\max(i,101-i)} \approx 1.38$$$
Since the size is halved at every stage, we have $$$\log 100 \approx 6.64$$$ layers. So very very roughly do we use $$$1.38 \times 6.64 \approx 9.16$$$?
I did a O(N) solution for E, will leave the explanation if interested. It has the same objective of the editorial explanation, looking for the final value for each i where frec[i] > k.
Observation 1: Given an i where frec[i] > k, none of the indices j > i, where frec[j] > 0, will be the final value for i. The reason is that each time a frequency is passed from an index to another, atleast k positions are passed. So if the next index has a frequency > 0, then it will be atleast k+1 and will continue passing it on.
Think of indices with frec[index] > 0, as Xavi Alonso's (football player), every time a ball is given to index, it will pass it to the next index.
Observation 2: All elements that passed values will always be > 0. This means we are only interested in the elements with frequency = 0, and once an element with frequency = 0, passes the ball (value), it will become greater than 0.
We have frequencies different than 1 and frequencies equal to 1. Let an array A be a path where A_i, passed its frequencies to A_{i+1}. Note that all elements except the last will equal to 1.
Implementation: Iterate from 3*N to 1. We will store the values with frequency different than 1, and the idea is to maintain a sorted array with elements from [i+1, 3*n] that have frequency != 1. If the ith element has frequency > k, then iterate the array and start checking if it can be an endpoint or not, and accumulate the total frequencies passed. Note that there will be 0s and elements greater than 1, one will be a possible endpoint the other will add more frequencies. 350497294
For Problem D, I believe using the median provides a simpler and cleaner solution. I would appreciate it if someone could review my implementation.
350522473
never thought I'd be able to see an easy Div2E (solvable by me) before GTA 6
We can actually analyze and solve problem F in a provably optimal way. The main idea is to analyze the problem the full tree of operations, instead of trying to construct the passes in blocks of $$$m$$$.
As in the editorial, we'll think of the state as a set of "alive values" which are possible. Each operation on must take an alive value $$$y$$$ and merge $$$y$$$ into the closest $$$y+l$$$ that's currently alive: there's no reason to pick a bigger $$$l$$$, since that wouldn't help us any more than just going to $$$y+l$$$, and there's no reason to pick a smaller $$$l$$$, since we could just delay the operation until we do merge $$$y+l$$$ (the relative order will never change, so the cost will be the same).
Let's fix the number of decreasing passes of operations as $$$d$$$, so that we pay $$$1000(d-1)$$$ for the passes.
Now, let's consider the (ordered) tree of merges of alive values over each pass. This tree should have $$$d+1$$$ layers, with $$$n$$$ leaves at the bottom, and each node's children form an interval of the next layer. A node's actual "alive value" is just the index of its rightmost leaf, since we always merge to the right; let the rightmost leaf of node $$$n$$$ be $$$r(n)$$$.
Now, let's analyze the total cost of the merges. Consider an interior node $$$n$$$ with children $$$c_0, c_1, \ldots c_t$$$. We have $$$r(n) = r(c_t)$$$, and we'll merge them from right to left over the pass and pay
We can simplify these differences, though: if we have $$$sz(n)$$$ be the number of leaves in the subtree of $$$n$$$, note that
Thus, the cost instead equals
Regrouping, we have the cost equals
Now, we can change the order of summation to group by each leaf. Let's label each leaf $i$ with an array $$$a_i$$$ of length $$$d$$$ corresponding to the path we take from the root to this leaf: leaf $$$i$$$ is in the $$$a_{i,j}$$$-th child at layer $$$j$$$. Then, the total cost of all operations is exactly
Thus, we can actually construct our tree by picking the smallest possible arrays $$$a_i$$$. After fixing $$$d$$$, we can construct at most $$$\binom{d + w - 1}{w}$$$ arrays $$$a_i$$$ with total sum $$$w$$$. We can pick them greedily, and then construct the tree afterwards.
For $$$n = 250000$$$, it turns out the optimal depth is $$$d = 113$$$ and the optimal cost is $$$855330$$$. This is the smallest depth where all leaves have weight $$$\le 3$$$.
Code: 350576854
That's cool! I think I would have used this version of the problem if I had come up with it.
Could somebody help me out in this problem, 2104D - Array and GCD in this question there is no constraints on coins if it is given that number of coins left in last should be zero. could somebody help me , as i am not able to think the solution,ecnerwala and TheScrasse
Simple answer is... You don't have to make final coins to be zero in the end.
Also please stop tagging LGM or GM for small doubts. You can use GPT or Gemini or any other LLM for understanding problem. Most of the time they are correct.
Don't make fun of my question, I have solved the question, and I think if a new question made in which if it is given that the coins left should be zero then what could be the solution , and I think so much but not able to find correct solution with a proof, I also use Gpt for this doubt, but the response was wrong and i have also discussed with my friends who are candidate masters on codeforces , could not able to solve this , so I asked here , if any humble person present here , please answer my query
Re-read your initial question. you clearly meant that you didn't understand this problem... anyways, next time, phrase your question better way.
if you know the answer of my query , then please answer
Didn't realise O(N) solution is already posted by someone for Problem E. My comment was redundant. removed for now. sorry.
DFS Round.
Hello. There is a typo in the editorial of problem H. "We can also transform a solution to (n,m) into a solution to (n+1,m+1)" should be "We can also transform a solution to (n,m) into a solution to (n+1,m)".
Here's my method for estimating the expected cost of problem G.
On the $$$i$$$-th layer of the trie. It divides the $$$n$$$ nodes into $$$2 ^ i$$$ parts. Consider what the MST of each part looks like.
Well, the longest edge connects the node with the minimum index and the maximum index, and then the node inside the range connects to the further node of the node with the minimum index and the maximum index.
In $$$i$$$-th layer, 'cause the testcases are generated randomly, we consider each part has a close number of nodes. So we consider each part has $$$\dfrac{n}{2 ^ i}$$$ nodes.
The range of the $$$k$$$ node randomly chosen from $$$n$$$ nodes is $$$r = \dfrac{k - 1}{k + 1}n$$$. For the other nodes, we consider the worst situation; the rest nodes are distributed near the middle of the range. So the distances are $$$\dfrac{d}{2}, \dfrac{d}{2} +1, \cdots$$$.
I used the following Python script to calculate it:
And the result is $$$9.140841614572105$$$.
https://codeforces.me/contest/2157/problem/C Can anybody explain where my code is wrong?
For E, this my O(n) solution.
Consider paving wave to the right. When paving way, either you create a new paved way, or you merged previous paved segments into one. So creating new and merging old paved way is in 2*n.
For element i with freq[i] (a = freq in code), you can stop if you finish pave freq[i] — k entries, and the total length of the paved way is the minimum number of operation (might merging with other paved road so that the final position of the bricks will be freq[i] — (freq[i] — k) = k.
Hopefully this can help you! Please let me know if further explanation is needed
hello, ik im quite late but in question c can anyone pls explain where i went wrong? where i messed up?
352570105
this is my submission void solve() { ll n, k, q; cin >> n >> k >> q; vector a(n, 0); vector<pair<ll, ll>> m; while (q--) { ll c, l, r; cin >> c >> l >> r; l--, r--; if (c == 1) { for (ll i = l; i <= r; i++) { if (a[i] == 0 || a[i] == 2) { a[i]++; } } } else { for (ll i = l; i <= r; i++) { if (a[i] == 0 || a[i] == 1) { a[i] += 2; } } m.pb({l, r}); } } vector ans(n, -1); for (ll i = 0; i < n; i++) { if (a[i] == 3) { ans[i] = 1000000000; } else if (a[i] == 1) { ans[i] = k; } else if (a[i] == 0) { ans[i] = 1000000000; } } sort(all(m)); f(i, m) { vector temp(ans.begin() + i.ff, ans.begin() + i.ss + 1); ll mi = mex(temp); if (mi == k) { mi = 1000000000; } for (ll j = i.ff; j <= i.ss; j++) { if (ans[j] == -1) { ans[j] = mi; temp[j — i.ff] = mi; mi = mex(temp); }
if (mi==k)
        {
            mi = 1000000000;
        }
    }
}
f(i, ans) cout << i << " ";
cout << endl;
}
my basic logic was sooo 4 cases on each index case 1: c=1 then ill put a[i]= k. basically it should be the min soo who cares if there are multiple k as long as there is nothing <k. case 2: i has no constraint, neither c=1 nor c=2 soo there i put a[i]=1e9. thats massive enough to not cause any issue anywhere neither with min nor with mex. case3: c=1&&c=2 that means i have to satisfy both mex and min, soo a[i]!=k. a[i]>=k cuz of this >=k then that means it can't help making mex =k soo i just put it a[i]=1e9. same logic with case 2. case 4: ill take mex and put the next 'non locked' index as that mex, now mex will increase by something based on what all stuff is present in the array. recalc mex and repeat. if mex=k i can't put k there soo again logic of case 2 put 1e9. (locked ones are case 1,2,3) non locked are the remaining ones btw
can anyone pls help me?
Hello, good day to you sir TheScrasse
sorry to disturb you sir, but can you please solve my doubt? in this question is my approach/logic wrong or is my implementation wrong?
This is similar to the editorial solution. The difference is "if mex=k i can't put k there soo again logic of case 2 put 1e9.", which is wrong. In fact, there might be other MEX constraints containing these elements, and putting 1e9 can make the other MEX constraints impossible to satisfy.
A good conpetition! they are interesting
a better code for the D problem since i find the editorial code difficult to understand,353609790
but the hints were good enough to get me through the idea
Solution of Adjusting Drones (Problem E)- Would anyone please tell which testcase it's giving error on ? 353740562
I don't think you can see the code
why is almost nobody talking about problem D solution using ternary search
In D, although it can be guessed, but editorial introduces out of the sudden concepts like red and blue element, which the task didn't even mention. Also, to complement editorial, I think the crucial insight is that for fixed x (p in description), the score can be written as linear function f(x)=ax+b
$$$(|3|-|2|)x+(\sum_{\in{2}}{a_i} - \sum_{\in{3}}a_i)$$$, where 2 is a set of elements assigned to 2nd option and 3 defined analogously. It becomes clear, why it's enough to check x=l and x=r (cases when a is positive and negative). It's not hard to notice that for fixed |2| and |3| counts, it's optimal to choose largest elements to 2 set and smallest to 3 set (constant part, the difference between max and min).
In 2nd Sketch of proof, it's not proven/mentioned that R B is always better than B R. In 3rd Sketch of proof, you might model 3 situations where the p is in middle, to the right of y and to the left of x. In all cases, the difference is y-x (positive).
One thing that I can't understand is that the provided solution roughly takes n/2 lowest elements as R (unless it's always guaranteed to be lower than l, similar for B) and n/2 highest as B (tries to make both sides as equal as possible). Why does this construction work? And the middle element is left as white in case of odd array length.
problem C : https://codeforces.me/contest/2157/submission/359948184 How to become better in implementation? help me with guidlines. I was tring to solve the problem and my idea of the solution actually the same which i have verified after getting wrong answer in test case 2 several times and ends up reading tutorials. In the tutorial solution what he did i actually wanted to do that but i tried to to it different implementation. I was quite surpriced to see the editorial solutions how simply he did it. can you have a look on my previous submission what did i do wrong?
my O(n) solution for E (it's possible to get rid of the deque and the pair but I'm just lazy):
A $$$O(n)$$$ solution to E
my O(n) solution for problem E. Adjusting Drones