Codeforces Round 1133 (Div. 1, Div. 2) is coming soon! Register here.
→ Pay attention
→ Streams
→ Top rated
| # | User | Rating |
|---|---|---|
| 1 | Benq | 3676 |
| 2 | Kevin114514 | 3659 |
| 3 | jiangly | 3640 |
| 4 | turmax | 3450 |
| 5 | tourist | 3382 |
| 6 | strapple | 3360 |
| 7 | Um_nik | 3354 |
| 8 | squareOf105 | 3348 |
| 9 | maroonrk | 3312 |
| 10 | idontwannadothis…e | 3191 |
→ Top contributors
| # | User | Contrib. |
|---|---|---|
| 1 | Qingyu | 155 |
| 2 | nik_exists | 151 |
| 3 | maspy | 149 |
| 4 | AmShZ | 145 |
| 5 | Um_nik | 143 |
| 6 | Errichto | 139 |
| 7 | BledDest | 136 |
| 8 | adamant | 134 |
| 9 | maroonrk | 132 |
| 10 | cry | 130 |
→ Find user
→ Recent actions


Codeforces (c) Copyright 2010-2026 Mike Mirzayanov
The only programming contests Web 2.0 platform
Server time: Nov/07/2026 09:38:05 (h1).
Desktop version, switch to mobile version.
Supported by


LLM do not really think, they just predict next token in sequence. Therefore this only shows, that range of simple tasks is somewhat limited. If problem setters every now and then switched to new vocabulary, that'd substantially reduce LLM success rate of solving such problems.
It seems you do not know what you are talking about, and you are underestimating next-token prediction. Predicting the optimal next token given an input is far from trivial. Furthermore, I believe you are outdated and unaware of the latest reinforcement learning methods applied to instruction-based models, which have made these systems genuinely capable of solving complex problems. I challenge you to test the model’s vocabulary and try to fool it. The median rating of a popular model that most users can access, without tools (terminal) , is approximately 2100; it can peak at 2300, and with the right tools it can even reach 2700. Please update your information before posting non sense.
Can you point me to good resources regarding the topic (reinforcement learning methods applied to instruction-based models)? Thanks.
Are you living that in that famous country where it is difficult to access most of the internet? If not, do you live under a rock?
o3 had been able to achieve 2700 ratings and it more or less holds up for 3 months already now. I am sure those who have the resources to call LLMs are already well aware of this and making the best use of it, constructively. The next time it would surprise me is when it starts solving div1E consistently (at consumer-viable cost).
(interpret the 2700 number with caution since in modern CF styles + most use cases + typical computation resources you can spend on it means you probably need to deduct at least 400 from it. I also had it catastrophically failing to implement rectangle union before, but I still feel it is generally that zone)
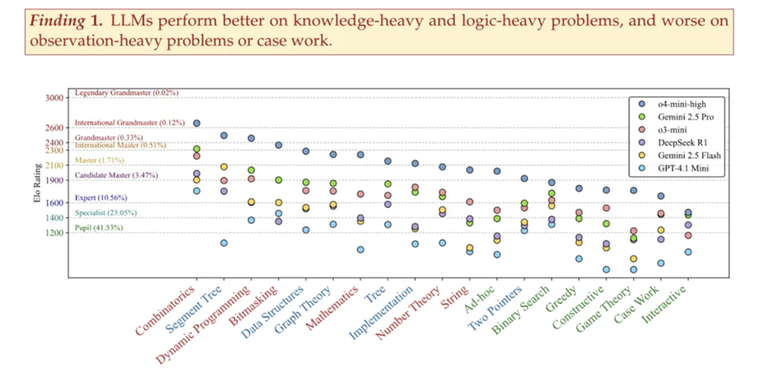
It’s nothing surprising—studies show that o4-mini-high excels on tags like combinatorics, data structures, and number theory (rated 2100–2700), not to mention o3 and o3pro (By the way, when the o1pro first came out just over six months ago, it could solve 2700-rated math problems in about a dozen minutes). For these kinds of problems, if you have the entire Internet as your knowledge base and ample computing power, many solutions can be derived mechanically. But look at AI’s performance on interaction, construction, game-theoretic, and greedy problems (rated 1500–1800)—it seriously lacks imagination and the ability to “guess.”