


I've checked today is not April 1st.
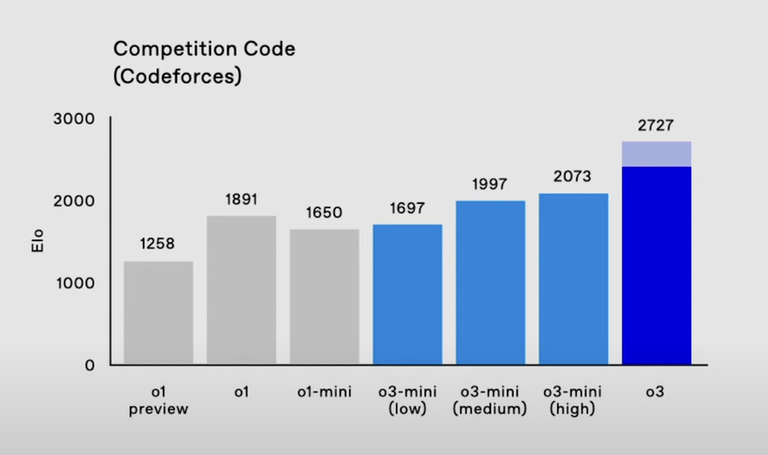
(source: 12 Days of OpenAI: Day 12 https://www.youtube.com/watch?v=SKBG1sqdyIU)


I've checked today is not April 1st.
(source: 12 Days of OpenAI: Day 12 https://www.youtube.com/watch?v=SKBG1sqdyIU)
| № | Пользователь | Рейтинг |
|---|---|---|
| 1 | jiangly | 3810 |
| 2 | Benq | 3676 |
| 3 | Kevin114514 | 3655 |
| 4 | maroonrk | 3463 |
| 5 | strapple | 3447 |
| 6 | Um_nik | 3387 |
| 7 | heuristica | 3322 |
| 8 | turmax | 3317 |
| 9 | tourist | 3307 |
| 10 | jiangbowen | 3291 |
| Страны | Города | Организации | Всё → |
| № | Пользователь | Вклад |
|---|---|---|
| 1 | Qingyu | 156 |
| 2 | nik_exists | 150 |
| 2 | maspy | 150 |
| 4 | Um_nik | 141 |
| 5 | Errichto | 139 |
| 6 | adamant | 137 |
| 7 | AmShZ | 135 |
| 8 | BledDest | 132 |
| 9 | maroonrk | 131 |
| 10 | qwexd | 129 |


Merry Christmas!
thanks for guiding me to become red
Please help me for the same! :')
Merry Christmas! ⛄
Common Sense
Anyone know why o1 is rated 1891 here? From https://openai.com/index/learning-to-reason-with-llms/ o1 preview and o1 are rated 1258 / 1673, respectively.
Benq do you think it's the end?
end for us mortal humans, not for gods...
At this rate, it will be over for these so-called gods soon. It is chess all over again.
what happen to chess will happen to cp too,but ppl still enjoys chess played by humans not some mere machines,
1891 was o1-ioi I think
hm, o1-ioi is only 1807 in the link I shared though
in 5 years, there will be no way to pretend that the average human is worth more than a rock
I'll wait until it starts participating in live contests and having Red performance
damn im cooked
Not possible...
I doubt that AI can do better math research than humans 5 years later.
That's the only thing you're gonna be able to do 5 years later — doubt.
Is this a prediction about humans now vs AIs in 5 years or AI + human in 5 years vs AIs in 5 years?
From the presentation we know, that o3 is significantly more expensive. o1-pro now takes ~3 minutes to answer to 1 query. based on the difference in price for o3, o3 is expected to be like 40-100?(more???) times slower. CF contest lasts at most 3 hours. How can o3 get to 2700 if it will spend all the time on solving problem A? It's very interesting to read the paper about o3, and specifically how do they measure its performance.
It must be parallelized. Surely there is something like MCTS involved
do you think it will remain 40-100 ? it will improve by the time and within 3-4 years there will be some another version may be o9-o11 and it's rating will be near Tourist and will be able to solve question within minutes.
I will personally volunteer myself as the first human coder to participate in the inevitable human vs AI competitive programming match.
I only believe it if it was tested in a live contest
Maybe, codeforces should allow some accounts from OpenAI to participate unrated in the competitions? MikeMirzayanov what do you think?
o1-pro was tested in this contest live https://codeforces.me/contest/2040 and solved E,F (the blog has since been deleted)
It also couldn't solve B after multiple attempts, so keep that in mind as well (still, it's really impressive)
It feels comfortable until your last line
I mean, I can't deny it, these new AI models are really impressive for what is, in essence, a "which word is likely to come next" model. With that being said, and I'm paraphrasing from what I've heard others say since I'm nowhere at the level to solve those problems, F was a knowledge problem of Burnside's lemma with a bit of a twist.
I can't say for certain how these models will evolve; o3 got a super high score on ARC-AGI (a general reasoning task set), which could help its performance on problems like B. On the other hand, we have no idea if these results are embellished or how exactly they're calculating this, so only time will tell.
Dude, I feel big threat
If o3 really has deep understanding of competitive programming core principles I think it also means it can become a great problemsetting assistant. Of course it won't be able to make AGC-level problems but imagine having more frequent solid div.2 contests that would be great.
Is this a real life?
Is this just fantasy?
caught in a landslide
no escape from reality
Open your eyes
look up to the skies and see
Im just a poor boy
I need no sympathy
Because I easy come
easy go
Little high
Little low
Anyway the wind goes, doesn't really matter
To me
Mamaaa, just killed a man
Put a gun against his head
Pulled my trigger, now he's dead
MaMa, Life had just begun.
But now I've gone and thrown it all away
MaMa, oh, didn't mean to...
make you cry...
If I'm not back again this time tomorrow
carry on, carry on...
How do these things perform on marathon tasks? Psyho
Last visit: 2 months ago
https://deepmind.google/discover/blog/funsearch-making-new-discoveries-in-mathematical-sciences-using-large-language-models/
this paper covers it, tldr it outperforms top teams on hashcode because it can come out with really good scoring functions and that's the focus of the parent paper called funsearch https://www.nature.com/articles/s41586-023-06924-6
опа привет Виталя
вот это встреча
I don't see why people are paranoid about those insane ratings claimed by OpenAI. I guess they're worried about cheaters, but why? Competitive programming isn't only about Codeforces — it's a whole community. In every school and country, we know each other personally, we see each other solve problems live, and we compete against each other in onsite contests. So we know each other's level. When we see someone who we know isn't a strong competitive programmer suddenly ranking in the top 5 of a Codeforces contest, it doesn't mean much. We just feel sorry for them that they've started cheating. It will be more funny when we see a red coder who can't qualify for ICPC nationals from their university.
i think you're not seeing the bigger picture, the implications for the competitive programming are huge. 1) we might lose sponsors/sponsored contests because now contest performance isn't a signal for hiring or even skill? 2) let's not kid ourselves, but a lot of people are here just to grind out cp for a job / cv and that's totally fine. now they will be skewing the ratings for literally everyone. 3) from 2 it may follow that codeforces elo system completely breaks and we'll have no rating? the incentive to compete is completely gone which will further drive down the size of the active community there are many more, i bet you could even prompt chatgpt for them :D
we'll have no rating
And then we will have no cheaters. Happy ending
It will be more funny when we see a red coder who can't qualify for ICPC nationals from their university.
It's not funny, it happens quite often, for example, at our university(
Red was just an example, A more accurate example would be a team of newbies qualifying while a team of reds fails to do so. don't tell me it's still not funny
Then their (grandmasters') life choice is wrong lmao
I think it has major implications for the whole world, not only competitve programming. For example, pace of mathematical research can easily double almost overnight (realistically over like a year period).
According to this article, it does not seem practical for the average user to run?
Quoting, "Granted, the high compute setting was exceedingly expensive — in the order of thousands of dollars per task, according to ARC-AGI co-creator Francois Chollet."
However, this is indeed a large step forward for AI.
It doesn't matter—SSDs weren't a common choice for the average user 15 years ago. Remember, technology develops exponentially. The cost of chips and electricity isn't the main issue; the key point is that it's possible. btw even cost of running that thing is 1 million per task, if it can solve open problem like P vs NP then people will pay even billion.
Do I still have a chance to reach LGM before AI?
OpenAI is lying. I bought 1 month of o1 and it is not nearly 1900 rating. It is as bad as me. I think they lie on purpose because they are burning a lot of money and they want people to buy their model.
True. I have tested o1 and yet it could barely solve most 1500~1600 tasks. I thought that maybe, since it's a language model, it would be better at solving more standard problems. But well, it also failed miserably in some (note: some, not all) quite well known problems. From what I've seen o1 can easily solve "just do X" type problems, and is pretty decent at guessing greedy solutions (when there is one). My guess is that openAI did virtuals with o1 in a bunch of different contests and claimed it to have the rating of the best performance between all these virtuals.
I hope so, but have you seen it solve Div2 E, F in the recent contests?
I think they mean o1-pro here. Yes it's not quite honest to say "o1" here. o1 is something like 1650 IIRC.
I'm a bit skeptical. o1 is claimed to have a rating around 1800 and I've seen it fail on many div2Bs.
If I already have lower rating than o1-preview, why should I be concerned?
after we have rank Tourist for 4000 ratings, maybe we can have GPT for 4500 or so in the near future.
WYSI
Cheers
727 no way
What does the light blue part on o3 mean here? Doesn't seem like the video explained it.
A lot more compute?
It means that AI didn't get it right in the first attempt.
Source: https://www.youtube.com/watch?v=YAgIh4aFawU&t=348s
Amazing and unbelievable!
I recently subscribed to o1 (not the pro version) in the hope of clearing out some undesirable problems in BOJ mashups, and I got skeptical if this AI is even close to 1600. It can solve some known problems, which probably some Googling will also do. However, in general, the GPT still gets stuck in incorrect solutions very well and has trouble understanding why their solution is incorrect at all.
So, how did the GPT get a gold medal in IOI? Probably because it was able to submit many times. So, if I give them 10,000 counterexamples, it will eventually solve my problem. Maybe I could also get GPT to do 1600-level results if I gave them counterexamples all the time.
In other words, GPT generates solutions decently well, but it is bad at fact-checking. But fact-checking should be the easiest part of this game: You only need to write a stress test. Then why is this not provided on the GPT model? I assume that they are just not able to meet the computational requirements.
I don't think the results are fabricated at all (unlike Google, which I believe fabricates their results) and believe even at o1 model GPT can find a good spot, especially with the recent CF meta emphasizing "ad-hoc" problems which are easy to verify and find a pattern. But this is a void promise if it is impossible to replicate in consumer level. I wonder if o3 is any different.
You can write the code yourself to prompt it to stress-test. I think that shouldn't be part of the default model served to users, it would add too much computation, while 99% of the time during dev use cases users will just feed untestable snippets.
People have already submitted o1-mini solutions in contest and gotten 2200 performance multiple times.
I have the o1 pro mode. It can solve problems with difficulty 1600-1700 and can solve some 1800s.
There are cases that it can't solve 1800 problems but its solution is on the right directions.
You all are missing a very important thing, o3 takes $100+ per task to compute
Since the scale is logarithmic, o3 high is pretty close to $10000
Yep, they're not replacing us any time soon
your comment gave me beaaaan
it will only last until 'soon' is over
Have you watched the AlphaGo documentary? It defeated Lee Seedol, who then resigned saying "there is an entity that can't be defeated"-it made Go meaningless for him.
I kinda feel the same way (tho i am not good, but still). If there is an entity that cannot be defeated no matter how hard i try, then it kinda makes it meaningless. The way i counter it is by thinking-no matter how good the AI is, it can ALWAYS be defeated by humans.
So, that 'soon' will never come-at least for me. Even if it reaches 5000 rating, i would still believe it can be defeated.
Sorry for the essay.
Well that certainly is an interesting way to look at it. I don't think it should become meaningless if AI becomes better than tourist. I think that, no matter how good AI becomes at math or chess, it will never have the type of awareness that would put it on the same level as people. So like, maybe it will always be worse at pure ad hoc contests.
Yeah, i also think you can always come up with easy ad-hoc problems that AI wont be able to solve. But with the recent developments, I am not sure about that either.
But either way, i would continue to believe that AI can always be defeated by humans, even in Go and Chess.
This is not for the Codeforces benchmark but for the ARC-AGI benchmark, where they set a new state of the art. Please watch from https://youtu.be/SKBG1sqdyIU?t=304 for more details. Here's the actual benchmark we're looking for:
According to https://youtu.be/SKBG1sqdyIU?t=670, o3 is actually more cost effective than o1. Here's a comparison based on openai's benchmark (Estimated by my eyes):
$0.22$0.1$0.82$0.17$0.3$2.15 + Δcp is P2W at this point
The cost scale is actually logarithmic
I wonder why you got downvoted. It is logarithmic. It costs like 3000$ per query for o3 with max compute (the one which scores 2727 I believe). They did not publish numbers for cp queries but they did so for ARC and I assume cp ones are not that different.
they did publish the numbers, read the comment above
even LGM afraid of this what should I do? raise pigs on the farm?
AI is the farmer and we are the pigs.
My efforts look like a joke to the AI.
very nice username, it was a good novel
So why there're two colors above o3 in the chart, I don't understand.
I have exactly same rating as o1-mini wow!
Not for long
yeah takopi will become far better than AI trash
I don't think o1 has 1891. I gave him an 1400 problem just now, but he failed to work out it after 20 tries.
it can solve 2400, but fail to solve 1200 sometime, it's quite wired
I think some 2400 problems are similar to other problems that GPT has already learned
That's right. I think GPT can't solve ARC & AGC Problems by itself now(if they didn't learned), some Ad-Hoc problems, GPT can't solve.
I think the o1 shown in the benchmark is actually
o1 prowhich I don't have access to. Here's theo1-miniresult from yesterday's contest tho:2049A - MEX Destruction [800] — 297608660
2049B - pspspsps [1300] — 297609098
2049C - MEX Cycle [1500] — 297609475
2049D - Shift + Esc [1900] — 297611240
Prompt used:
Solve in C++, USE MORE REASONING TOKEN, DO NOT GIVE UP, DO NOT STOP THINKINGHow many tries did it take? Did you correct it when (if) it failed on some test cases?
So what supports their claim of "Elo 2727"? (Apologies if it's included in the video cuz I donot have trivial access to youtube) Last time they claimed o1-mini to be CM level but it could solve only hell classic problems.
I am wondering too. Which account is OpenAI using to participate in the contests?
Nothing. "Just trust me bro". Although personally, I do trust them given that it's very expensive (around 3000$ per query I believe). They say o3-mini will be released in late January, so we will be able to check at least small model results soon.
So 1 prompt costs 3000$????
tbh cost will become irrelevant, it's all about chips and cost of electricity. chips will be cheaper and they will build dedicated nuclear power plants for training. then it will be cheap as o1.
insane
Why do people scare of A.I situation a lot though, since these contest/platform was mostly born for us to study CP, to compete in a peered Contest.
The A.I being good, then it most likely the same situations with a student and his mentor ?
I don't really understand if this is any threat at all. Feel free to inform me, if I'm wrong, I appriciate it a lot !
No. Over half of the people here (and much more in the whole society) are not genuine CP lovers. They will use AI for malicious purposes and we cannot stop them.
Should i start codeforces? Or leave
I guess we should until......
Reddit post with source i think?
Idk, checked the submissions and it seems quite human, but we'll wait and see. Also, please keep in mind that it's only confirmed if it actually performs at 2700 in a real contest, because learned problems are well... part of the training set.
Edit: Nvm, did not watch video.
According to the account which the gpt-o3 use, it participate in just 10 contest and cross 4 years.
And currently in codeforces, if you do not submit any code during contest, the contest will unrated to you.
So if there is a another strong person who monitor the gpt, and gpt finish the code first, and if it not perform good, it just not submit the code, it will be easy to get the high rated.
Maybe should wait a more reasonly benchmark, like continously 10 contests that it perform good.
In chess ai engines outperform humans but that does not mean that people have stoped participating.
Similarly, the world of competitive programming will adjust.
chess is a sort of entertainment that people can watch so it survived, not sure about cp
I think it's a good tool for someone who wants to study on their own, but don't cheat during the contest (sorry for my bad english)
My birthday!
Тбрик
I believe that although gpt can solve problems as high as 2700,it might just be as stupid as me.It seems that it only can solve problems similar to what it learned and never able to solve ad-hoc ones.
Openai recently published a paper where they shared their codeforces benchmark details
You can view the pdf here: https://arxiv.org/abs/2502.06807 | Here's their simulated contest participation on codeforces:
Pinely Round 3 (Div. 1 + Div. 2)
Good Bye 2023
Hello 2024
CodeTON Round 8 (Div. 1 + Div. 2, Rated, Prizes!)
Codeforces Round 934 (Div. 1)
Codeforces Global Round 25
Codeforces Round 941 (Div. 1)
Codeforces Round 942 (Div. 1)
Codeforces Round 947 (Div. 1 + Div. 2)
Codeforces Global Round 26
EPIC Institute of Technology Round August 2024 (Div. 1 + Div. 2)
Codeforces Round 969 (Div. 1)
Average performance (According to carrot) seems to be around 2836 over these $$$12$$$ contests
Horrible, I don't want to see CP dying from AI...
They made a benchmark of CP to measure models' reasonning ability. And because of the benchmark, they will contribute to collect massive data from the platform and enhance the CP performace... Under the competitive atmosphere of generative ai, it wouldn't be a shocking news that AI reach LGM in months.
Amazing! Can't wait until all cheaters start using it!
lol how is $$$I$$$ $$$1900$$$?
rainboy
that is possible
The most important thing here to note is that its the machines that are living in the digital world created by us, not the other way round. Machines, without consciousness, are just complex calculators. Humans competing with tools, is like a kung fu master competing with an axe, in wood cutting competition. Axe will always cut better than hands, but its just an axe.
This doesn't change the fact that AI is better than most people and can be used by almost anyone to cheat