Блог пользователя M_Sameer

Автор M_Sameer, история, 6 недель назад, По-английски

Hey everyone,

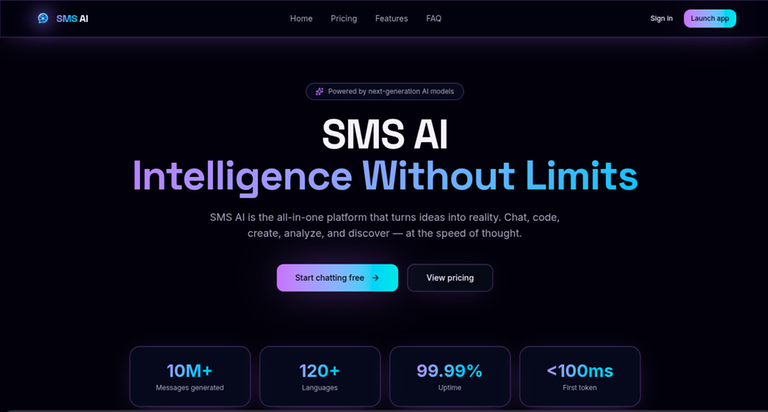
I wanted to share a project I’ve been working on called SMS AI.I love using LLMs, but I absolutely hate the latency. Waiting for a slow UI to stream code tokens line by line kills my rhythm when I'm in the zone. My main goal with SMS AI was to build an elite, highly responsive multimodal workspace focused on extreme speed—aiming for a time-to-first-token of under 100ms.Here is what is currently packed into the dashboard:Real-time Streaming Chat: Built-in markdown rendering and long-term memory that doesn't forget your context.Code Generator: Rich syntax highlighting, instant code refactoring, and logic explanations.Direct File Analysis: You can drop PDFs, TXT, or DOCX files straight into the workspace to parse docs instantly.Web-Aware Research: A dedicated search mode that crawls live sources and drops cited summaries so you don't have to open 20 tabs.The platform is fully global with 120+ language profiles supported, and I've set up a completely free tier (10 chat messages per day) so anyone can jump in and test the speed instantly.

Try it free here: SMS AI

Give it a try, try to break the code interpreter, and let me know your most brutal feedback on the technical issues or speed!

Полный текст и комментарии »

  • Проголосовать: нравится
  • -22
  • Проголосовать: не нравится

Автор M_Sameer, история, 6 недель назад, По-английски

SMS AI Platform Screenshot

Hello Codeforces.

Recently, I have been building a project called SMS AI. It is a simple but fast multimodal workspace to chat, generate code snippets, and parse documents.

Now it has major update.

I noticed that a lot of general web tools have quite high latency when streaming code blocks or rendering formatting properly. I wanted to see if I could optimize the processing structure to bring the time-to-first-token down under 100 milliseconds.

Полный текст и комментарии »

  • Проголосовать: нравится
  • -16
  • Проголосовать: не нравится

Автор M_Sameer, история, 7 недель назад, По-английски

Hey guys,

Like most people here, I use LLMs daily to double-check algorithms, write boilerplate, or parse through massive documentation. But I absolutely hate the latency. Waiting for a slow UI to stream code tokens line by line kills my rhythm when I'm in the zone.

I wanted something built for pure speed and utility, so I ended up building an all-in-one multimodal AI workspace called SMS AI.

The core focus is performance. The time-to-first-token is sub-100ms, so the streaming starts basically the instant you hit enter.

What's actually under the hood right now:

Real-time Streaming Chat: Built-in markdown rendering and long-term memory that doesn't forget the context of your codebase mid-session.

Code Generator: Fully optimized syntax highlighting, refactoring, and logic explanations for when you're debugging deep nested loops or data structures.

Direct File Analysis: You can drop PDFs, TXT, or DOCX files straight into the workspace to parse docs or API references instantly instead of scrolling manually.

Web-Aware Research: A dedicated search mode that crawls live sources and drops cited summaries so you don't have to open 20 tabs.

Other stuff: Built-in image generation and a voice assistant (hands-free if you get tired of typing).It's entirely free to use (10 requests/day, no credit cards or weird hidden catch). I really want to see how the streaming latency holds up under real competitive programmers pushing it with heavy, complex logical prompts.

Give it a run, try to break the code interpreter, and give me your most brutal feedback on the interface or speed. Link: SMS AI

Let me know what features are missing or what I should optimize next. Cheers!

Полный текст и комментарии »

  • Проголосовать: нравится
  • -15
  • Проголосовать: не нравится

Автор M_Sameer, история, 2 месяца назад, По-английски

Hey everyone,

Like most of you, I got sick of having five different browser tabs open just to cross-reference documentation, debug compiler errors, search the live web, and format text strings. I wanted a single, fast workspace that kept state intact.

So I built SMS AI. No corporate marketing fluff, just tools that work in a unified panel.

What it actually handles right now:

  • Zero-Lag SSE Streaming: Chat renders line-by-line instantly. No jumping UI containers or typing layout stutter. Full Markdown and code-block parsing.
  • Live RAG Pipeline: Drop in raw text, PDFs, or spreadsheets. It chunks data locally on a worker thread and runs instant extraction summaries without blocking the primary browser window.
  • Live Web Interleaving: Searches the live web and merges clickable, structural source citations directly inside code explanations.
  • Contextual Media: Generates visual layouts inside the thread and has an inline voice recording toggle for hands-free debugging loops.

The Architecture Setup:

  • Frontend: React + Vite + Tailwind CSS. Kept the stylesheet bundle extremely lean so the virtual DOM initializes instantly even on bad connections.
  • Backend Layer: Powered by native Supabase configurations to protect user session states and auth loops safely.

The platform has a genuine free tier (10 daily message credits, no credit card required) because I want people to actually use it and try to break it.

What I need from you:

I want to push the performance and stream rendering to the absolute limit next. Throw your nastiest edge cases, massive legacy codebases, or complex data spreadsheets at it and tell me where it bottlenecks.

Roast the interface layout, tell me what feels sluggish, or suggest what features I should inject next. I'll be hanging out in the comments to talk through the backend logic or handle code questions!

Cheers.

Полный текст и комментарии »

  • Проголосовать: нравится
  • -18
  • Проголосовать: не нравится

Автор M_Sameer, история, 2 месяца назад, По-английски

Hi Codeforces,

First of all, a huge thank you for the response to my last post! Because of this community, the app quickly crossed over 100 users, and your feedback helped me see exactly what needed fixing under the hood.I just pushed a major performance update to the live application SMS AI:

Zero Jitter Code Streaming: Completely optimized how code blocks and text streams onto the screen. It now scrolls line-by-line instantly with zero text jumps or client-side stuttering.

Instant Form Controls: Fixed the input box triggers. When you press Enter to submit a complex competitive programming problem sheet, it registers immediately with no awkward delays or temporary freezing.

Lightweight Virtual DOM: Cleaned up the stylesheet bundle weights so the entire multi-modal workspace loads instantly on slow or restricted networks.The platform is still 100% free to start (10 messages a day, no credit card required).Please try throwing some tough optimization tasks or algorithmic editorials at the code generator and let me know how the speed feels now.

I'll be in the comments tracking your feedback!

Полный текст и комментарии »

  • Проголосовать: нравится
  • -4
  • Проголосовать: не нравится

Автор M_Sameer, история, 2 месяца назад, По-английски

Hey Codeforces, During recent rounds, I found myself spending too much time parsing complex problem statement constraints and hunting down hidden runtime errors (like segmentation faults or subtle logic bugs) during post-match virtual contests. To speed up this workflow, I put together SMS AI — an ultra-fast, multimodal AI workspace built specifically to handle complex logic, debug runtime execution issues, and break down problem sheets instantly. Why it's useful for competitive programming:Blazing Fast Responses: Sub-100ms time-to-first-token. When you are rushing to fix a bug, you don't have time to wait for a slow UI. Deep Code Generation & Refactoring: Fully understands rich syntax highlighting across all major CP languages (C++, Java, Python). Document Analysis: You can feed it problem PDFs, statements, or input/output text files to quickly extract edge cases or hidden constraints you might have missed.I built this platform to handle intensive text and code structures at the speed of thought. It has a completely free tier (10 high-speed messages/day) which is more than enough to test out during your post-contest upsolving.Would love to get your feedback on how it handles complex C++ templates or weird runtime errors you've run into. Let me know what features or CP-specific tools I should add next!

Полный текст и комментарии »

  • Проголосовать: нравится
  • -8
  • Проголосовать: не нравится

Автор M_Sameer, история, 2 месяца назад, По-английски

Hey everyone, Following up on my previous build log, I have just pushed a major architectural update to SMS AI by Deltacoders to separate free computational tiers from premium processing workflows: SMS AI Thanks to the feedback from the community, the platform now handles multimodal text-to-image prompts using a dynamic tiered structure to keep performance ultra-fast for everyone. What's new in this system update:Free Tier Inline Generation: Free users can now generate images directly inside the standard conversational chat history panel. This operates on a highly optimized, lighter execution model labeled as GPT-2 Access Mode.Pro Mode Premium Suite: Subscribed users ($20/mo) now get access to a dedicated, separate Advanced HD Image Pop-up Window. This panel routes requests directly to a hyper-realistic GPT-5 Pro / Advanced Engine for blazing-fast, uncompressed visual generations.Optimized Code Engine: General syntax highlighting parameters, multi-file data loading speeds, and structural state routing have been streamlined for sub-100ms processing thresholds.You can test out the free inline generation directly inside your active chat stream right now with no registration data or credit card required.I would love to get your thoughts on the new dual-engine setup! Let me know in the comments how the image generation contrast or streaming performance feels compared to standard models. How does it seems.......? Will it be helpful for advance coders?.....

Полный текст и комментарии »

  • Проголосовать: нравится
  • -1
  • Проголосовать: не нравится

Автор M_Sameer, история, 2 месяца назад, По-английски

Hey guys,I wanted to share a project I've been grinding on lately called SMS AI.Before anyone asks, I want to clarify how it was made. I actually wrote the code and built the backend systems myself. I did not use an AI generator to spit out the project. I only utilized Lovable as a compiler and environment to run my code, test the preview layout, and push it live to a URL.My biggest goal was to get rid of that annoying delay you get with normal wrappers. Right now, it streams code blocks and answers with under 100ms first token response latency, which feels incredibly responsive.Features included:A code generator that highlights algorithmic scripts instantly.Document reading tool powered by global edge connections.Multi-modal chat with streaming memory.It is live on Product Hunt right now because I want to look closely at my custom admin dashboard metrics under a heavy traffic spike. I would really appreciate it if you guys could throw your most complex recursion, graph problems, or crazy edge cases at it to see if the engine chokes or slows down. Also give comments. Is it helpful or not..!

Полный текст и комментарии »

  • Проголосовать: нравится
  • -21
  • Проголосовать: не нравится