


Hello, Codeforces! As you know, most modern services actively use recommendation systems (e.g. instagram feed, tik-tok, personalized offers in banks, recommendations in shipping offers and marketplaces). I thought it would be interesting to do something similar with problems on codeforces, to make it easier to find interesting tasks for the user and simplify the compilation of personal workouts and mashups. Here is my recommendation system of tasks on Codeforces
The way the system works now looks like this: $$$\newline$$$ 1. For each user I calculate a vector of solved tasks tags (i.e. for each possible tag, the number of tasks with that tag solved by the user).$$$\newline$$$ 2. Normalize this vector. Let's call the result $$$\mathbf{u} = \frac{\sum\limits_{p \in \text{solved}} \mathbf{t}_p}{\left| \sum\limits_{p \in \text{solved}} \mathbf{t}_p \right|}$$$ $$$\newline$$$ 3. For each unsolved problem $$$i$$$ we take its binary tag vector $$$t_i$$$ and calculate the cosine similarity: $$$\text{sim}_i = \frac{\mathbf{t}_i \cdot \mathbf{u}}{|\mathbf{t}_i| \, |\mathbf{u}|} = \frac{\mathbf{t}_i \cdot \mathbf{u}}{|\mathbf{t}_i|}$$$ $$$\newline$$$ 4. For each problem we calculate its popularity: $$$\text{pop_norm} = \frac{\text{pop} - \text{pop}_{\min}}{\text{pop}_{\max} - \text{pop}_{\min}}$$$ where task popularity(pop) is the number of AC solutions, $$$\text{pop}_{\min}$$$ — the number of AC solutions for the task with the lowest number of solutions, $$$\text{pop}_{\max}$$$ — the number of AC solutions for the task with the highest number of solutions.$$$\newline$$$ 5. We consider that the user is more comfortable solving tasks close to his own rating: we use a Gaussian function: $$$\text{score}_{\text{rating}} = \exp\left( -\frac{(r_{\text{task}} - r_{\text{user}})^2}{2\sigma^2} \right), \quad \sigma = 0.3 \cdot r_{\text{user}}$$$ $$$\newline$$$ 6. We rank the tasks by the total rating equal to: $$$\alpha \times sim_i + \beta \times \text{pop_norm}_i + \gamma \times \text{score}_{raiting}$$$
The project is an opensource project, you can find all the source code in the repository. I am open to suggestions for improvement! Contributions are welcome! Feel free to open issues or submit pull requests!


.
Recommendations are based, in particular, on the proximity of the user rating to the task rating (see point 5 in the post).
It would be great to have an option for the opposite as well. I'm not sure how useful it is to keep recommending problems in tags you're already good at—solving problems in areas you're weak in might be more helpful for improving overall.
Good point! Exploration vs explotation dillema is really relevant here. That's why I form recommendations not only on the basis of tags, but also on the basis of task popularity and rating (which means that even if a task is not very similar in tags to what you usually solve, but very popular — it will be in your top).
Other approaches to solve this dillema will also be implemented in the future!
Wouldn't this just mean setting $$$\alpha \lt 0$$$ in the total rating formula
internal server error
looks nice ty for your service
It would be great if somehow we can base problem recommendations on topic the user is bad at. This data can be accessed like how the tle bot is able to tell the average speed of a user for a particular rating of problems (we can do the same for the tags). As well as analysing the contests where the user lost rating. (like easiest unsolved problem). As well as the problems where the user was slower than usual etc.
The idea is fun, and it's clear that you tried to draw inspiration from how recommendation systems work for social media. But your chosen interpretation doesn't really make sense in many cases.
Counting the number of problems with a given tag is reasonable, but not how you normalize it. There are a lot more problems with dp tag than with 2sat tag, so the fact that a person has 50x more dp problems solved than 2sat problems solved doesn't mean that they are better at dp or that they like dp more. It just means that there are more dp problems. So I would expect your normalized tag vector to be roughly the same for all experienced enough participants, with slight personal flavour and maybe some changes because of the person's rating, since some topics are rare outside of hard tasks.
Popularity is just difficulty. It's so obvious that I don't really know why you used it.
I get that you tried to model this on social media platforms where "you like something" or "something is popular" measured by the number of interactions with the subject, and it is tempting to use "solved" as the substitution for interaction for CP. Unfortunately, it stops making any sense.
Thanks for the critique! I agree with you on everything, I really should think about the interpretability of metrics in the context of CF. I will post a modified version soon!
Popularity is not always = difficulty, some problems are linked in the educational articles (cp-algorithms, etc) and thus more popular.
Quite a nice project! I like how you used actual recommendation algorithms for this. The only downside is that I do not know of any objective metric that can test how good a recommendation is.
However, the main advantage of any problem recommender is that you will be less likely to skip problems you do not like and have to solve them, which will help people improve more as they do not only do problems they are comfortable with.
Cool idea (and cool maths), but I see 3 main issues:
This emphasizes your strengths, which doesn't really help since you want to improve on what you are bad at not what you already can solve.
The "popularity" statistic depends on way too many factors such as contest timing, problem difficulty, and contest division to be useful, so I recommend removing it altogether.
The system recommends problems at the level of your rating, but since you usually want to improve instead of staying the same, it should use a customizable rating instead. This also addresses the issue of people being much better at CP than their rating suggests.
Nice project. An idea for recommendations: use user vector to search users with similar vectors, and unsolved problems among problems they solved. I believe there are some clusters, of problem preferences and for each a pool can be built offline, then just quickly classify user and select problem from his cluster
You could also add a feature in which, the problems that the user is weak with will be the one recommeneded, Rather than using $$$sim_i$$$, just using $$$1-sim_i$$$, will give the dissimilarity, and another thing you could do for this is that, while calculating $$$u$$$, you could give a negative weight for each tag in a problem that was attempted but is unsolved by the user, just a suggestion, not even sure if i'm correct ;-;.
Other than that loved the project and how you actually calculated the formula!!
Can you put an option to change my rating? I dont want 1500 tasks to show up.
When I search jiangly (idk why), it gives a bunch of errors.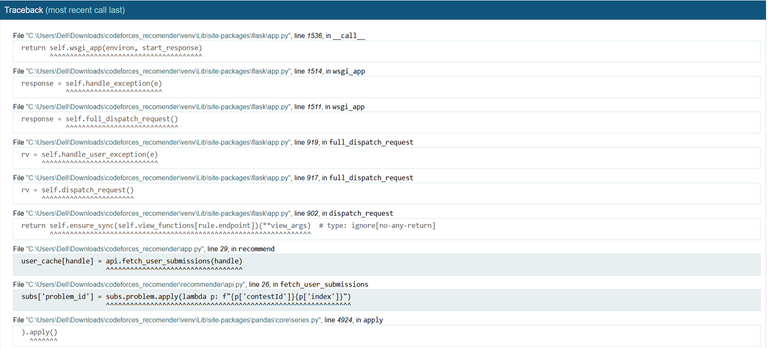
simply jiangly isn't human